WorldModels:Tutorial
lastmod 2026-11-18created 2026-11-173 edits
World Model Tutorial is a 15-chapter guide written so that a machine learning beginner can work through World Models in deep learning from start to finish on their own. It builds up probability, information theory, deep learning, and reinforcement learning in turn, then implements everything up to Dreamer, which learns to swing up a pendulum in imagination from nothing but 64×64 images, directly in PyTorch. This page is a map of the tutorial; each chapter has its own summary page.
- Original: World Model Tutorial (pages.unwiki.net)
- Setting: a single pendulum swing-up environment is used from start to finish. At first it is observed as 3 numbers, and from Chapter 8 on as 64×64 grayscale images.
- Derivations do not skip lines, and every key concept is checked with code that was actually run and the figures it produced.
World Models in one sentence
A World Model is a neural network trained to predict "what will happen next if I take this action in the current state". With such a predictor, an agent can simulate ahead in its head without actually trying things, and use that imagination to make plans or learn behaviors.
\((s_t,\ a_t) \;\xrightarrow{\ \text{World Model}\ }\; (\hat{s}_{t+1},\ \hat{r}_t)\)
The simplest form trains a neural network so that the prediction \(\hat{s}_{t+1}\) is close to the true value \(s_{t+1}\). The storyline of the tutorial is adding abilities to this one at a time: "seeing images", "capturing uncertainty", "remembering over long time spans", and "learning behaviors in imagination".
Contents
The tutorial is divided into four stages, and each stage provides the material for the next.
Stage 1: Foundations (Chapters 01 – 05)
By the end you can explain why World Models are needed, compute Gaussians, maximum likelihood, and KL divergence by hand, train a neural network in PyTorch, and derive the Bellman equation.
- 01. What Is a World Model - The intuition of a simulator in your head, models in reinforcement learning, model-free vs. model-based, Dyna, history, taxonomy, and four challenges.
- 02. Math ①: Probability and Maximum Likelihood - Random variables, joint and conditional probability, Bayes' theorem, expectation and variance, Monte Carlo, the Gaussian distribution, maximum likelihood estimation, and what MSE, BCE, and cross-entropy losses really are.
- 03. Math ②: Information Theory and KL Divergence - Information content, entropy, cross-entropy, KL divergence, Jensen's inequality, the closed form of the Gaussian KL, mutual information, and a preview of the ELBO.
- 04. Deep Learning and PyTorch Basics - Derivatives and the chain rule, gradient descent, backpropagation by hand, Adam, overfitting, CNNs, and transposed convolution.
- 05. Reinforcement Learning Basics - MDPs, returns, value functions, the Bellman equation, value iteration, REINFORCE, actor-critic, reparameterization gradients, and POMDPs.
Stage 2: The First World Model (Chapters 06 – 07)
Build a model that looks at a numeric state and predicts the next state, then plan inside that model to actually swing the pendulum up.
- 06. Your First World Model - Deriving the pendulum's equation of motion, Euler integration, an MLP dynamics model, standardization and predicting changes, open-loop rollouts, and error accumulation.
- 07. Planning in Imagination: MPC and CEM - Model predictive control, random shooting, the cross-entropy method, model exploitation, probabilistic ensembles, and PETS.
Stage 3: World Models That See Images (Chapters 08 – 10)
Compress images into small latent vectors, predict the future in latent space, and learn behaviors inside the "dreams" the model has.
- 08. Building the Eyes: VAE - Latent variable models, two derivations of the ELBO, the closed-form KL, the reparameterization trick, implementing a convolutional VAE, β-VAE, and posterior collapse.
- 09. Building Memory: RNN and MDN-RNN - RNNs, BPTT and vanishing gradients, LSTM and GRU, mixture density networks, log-sum-exp, temperature sampling, and dreaming in latent space.
- 10. World Models (Ha & Schmidhuber) - The V · M · C architecture, deriving the gradient of evolution strategies, implementing CMA-ES, training in the real environment vs. training in the dream, and temperature and model exploitation.
Stage 4: Learning in Imagination and Modern Models (Chapters 11 – 14)
Derive the training objective of the RSSM (the sequential ELBO) yourself, implement Dreamer to swing up the pendulum from images alone, and understand where the modern families of World Models stand.
- 11. RSSM and PlaNet - Latent state-space models, the five components of the RSSM, deriving the sequential ELBO, free nats, CEM in latent space, implementation, and results.
- 12. Dreamer: Learning Behaviors in Imagination - Imagined trajectories, n-step and λ-returns, actor learning by differentiating back through the dynamics, and the techniques of DreamerV2 and V3.
- 13. A Map of Modern World Models - MuZero, TD-MPC, Transformer World Models, diffusion World Models, JEPA, and large-scale video and interactive World Models.
- 14. Appendix: Debugging, Glossary, Next Steps - A debugging checklist, numerical stability formulas, a hyperparameter reference table, key formulas by chapter, a glossary, a map of papers, and public implementations.
How to read
| Path | For | How to read |
| A. Intuition path | When you want to grasp the concepts quickly | Read only the explanations, figures, and key-idea boxes of Chapters 01, the first part of 05, 06, 08, 10, 12, and 13, and look only at the result lines of the derivations. |
| B. Math path | When you want to be able to read the papers | Read every chapter in order, copying each derivation onto paper line by line, and work through the review questions. |
| C. Implementation path | When you want to build it yourself | In addition to B, run each chapter's code yourself and do the "Try changing it" experiments. |
If you get stuck on a formula, go back to Chapters 2 and 3 to review the relevant concept, and look up unfamiliar terms in the glossary of the Chapter 14 appendix.
What you need
Background knowledge
- Python basics: enough to read variables, functions, for loops, lists, and classes.
- High school math: functions, exponents and logarithms, graphs, and simple derivatives.
- You do not need to know linear algebra, probability, calculus, deep learning, or reinforcement learning. Chapters 2 – 5 explain as much as needed from scratch.
Computer
- Windows, macOS, or Linux all work, and 8 GB of memory or more is enough.
- No GPU is needed up to Chapter 10. Chapters 2 – 7 take a few seconds to 20 minutes on a CPU, and Chapters 8 – 10 take 20 minutes to 1 hour on a CPU (2 – 15 minutes on a GPU).
- Chapters 11 and 12 (PlaNet and Dreamer working from images) require a GPU. Each takes 45 minutes to a little over an hour on a laptop GPU (8 GB), and more than a day on a CPU.
- Each per-chapter hands-on file has a scaled-down
--quickoption that finishes in a few seconds to a minute (exceptch13_numbers.py, which finishes in a second anyway).
Installation
Python 3.10 or later is required.
python --version          # Python 3.10 이상인지 확인 (macOS · Linux 는 python3)
mkdir world-model && cd world-model
python -m venv .venv       # 이 폴더 전용 Python 환경 만들기
source .venv/bin/activate  # Windows 는: .venv\Scripts\activate
pip install torch numpy matplotlib   # 또는: pip install -r requirements.txt
python -c "import torch; print(torch.__version__, torch.cuda.is_available())"
The minimum versions in requirements.txt are torch>=2.2, numpy>=1.26, and matplotlib>=3.8. To use an NVIDIA GPU, pick the command for your environment in the PyTorch installation guide and install the CUDA build of torch.
Hands-on code
Each chapter's code is in the original's code/ folder (download files such as wm_envs.py from under https://pages.unwiki.net/world-model/code/). Put all downloaded files in the same folder and run them from there; figures produced by the hands-on files are saved to figures/ under that folder. Later chapters' files import earlier chapters' files or their results, so run them in order.
Run times were measured with default settings on a 4-thread laptop CPU and an 8 GB laptop GPU.
| File | Chapter | Prerequisites | Run time |
| | From 4 | - | A few seconds (the pendulum environment; every hands-on file that uses the pendulum imports it) |
| | 02 | - | CPU a few seconds |
| | 03 | - | CPU a few seconds |
| | 04 | - | CPU 3 – 6 min |
| | 05 | - | CPU under 30 s |
| | 06 | - | CPU about 1 min |
| | 07 | The | CPU 6 – 10 min |
| | 07 | The | CPU about 20 min |
| | 08 | - | GPU 2 – 4 min / CPU about 50 min |
| | 09 | Results produced by running | GPU 2 – 3 min / CPU about 20 min |
| | 10 | Results produced by running | GPU about 15 min / CPU about 1 hour |
| | 11 | - | GPU about 1 hour (CPU more than a day) |
| | 12 | The | GPU about 45 min (CPU more than a day) |
| | 13 | - | CPU 1 s · about 2 min |
If you run only the environment file first, a single pendulum image for checking is saved as pixel_pendulum.png in the folder you ran it from.
$ python wm_envs.py
상태 관측 (201, 3) 행동 (200, 1) 보상 합 -1071.9
그림 관측 (201, 64, 64) uint8 값 범위 0 255
pixel_pendulum.png 저장
The pendulum environment
All exercises take place in a small world called pendulum swing-up. The physics is the same as OpenAI Gym's (now Gymnasium's) Pendulum-v1, but it was implemented from scratch in numpy alone so that gymnasium does not need to be installed. The equation of motion is derived from Newton's laws in Chapter 6.
- State: the angle \(\theta\) and angular velocity \(\dot{\theta}\) of the rod. At \(\theta = 0\) the rod stands straight up, and at \(\pm\pi\) it hangs straight down.
- Action: the torque applied at the pivot, \(u \in [-2, 2]\).
- Reward: \(r = -(\theta^2 + 0.1\,\dot{\theta}^2 + 0.001\,u^2)\). The maximum value of 0 is received when the rod stays still at the top.
- Observation: the numeric version
Pendulumgives \([\cos\theta,\ \sin\theta,\ \dot\theta]\) (Chapters 5 – 7 and 13), and the image versionPixelPendulumgives the same pendulum as a 64×64 grayscale image (Chapters 4 and 8 – 12). - What makes it hard: the torque limit (2) is weaker than the torque gravity exerts on the rod (at most \(mgl/2 = 5\)), so the rod cannot be lifted in one go. It has to be swung back and forth like a swing to build up energy before it can be balanced upright.
- One step is 0.05 seconds, and one episode is 200 steps (10 seconds). Angular velocity is clipped to ±8 rad/s.
- Figure: The pendulum environment seen as 64×64 grayscale images (random actions, every 25 steps)
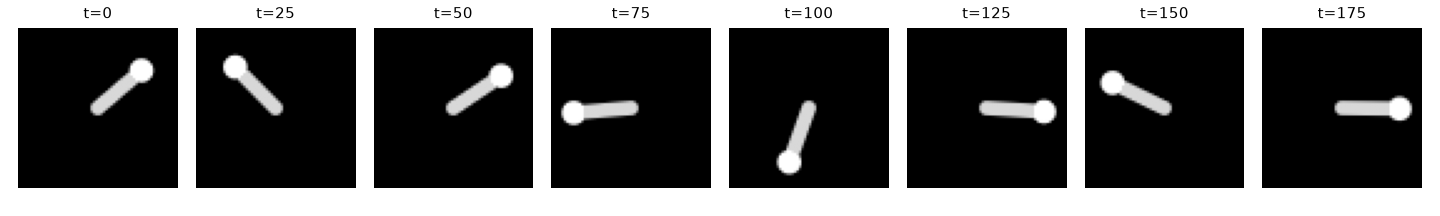
The three lines inside step() (updating the velocity, clipping the velocity, updating the angle) are the entire physics of this world. The World Model never sees these three lines and has to learn a similar function from (state, action, next state) data alone.
    def _obs(self) -> np.ndarray:
        # θ 를 그대로 주지 않고 (cos θ, sin θ) 로 주는 까닭:
        # θ = π 와 θ = -π 는 같은 자세인데 숫자로는 2π 나 떨어져 있다.
        # cos · sin 은 이 '이음매' 가 없어서 신경망이 배우기 쉽다.
        return np.array([np.cos(self.th), np.sin(self.th), self.thdot], dtype=np.float32)

    def step(self, action) -> tuple[np.ndarray, float, bool]:
        u = float(np.clip(np.asarray(action, dtype=np.float64).reshape(-1)[0], -self.max_torque, self.max_torque))
        th, thdot = self.th, self.thdot

        # 보상은 '움직이기 전' 상태로 계산한다 (Gym 과 같다).
        cost = angle_normalize(th) ** 2 + 0.1 * thdot**2 + 0.001 * u**2

        # 물리: θ̈ = (3g / 2l)·sin θ + (3 / m l²)·u     (6장에서 유도한다)
        # 오일러 적분: 속도를 먼저 갱신하고, 새 속도로 각도를 갱신한다 (semi-implicit Euler).
        thdot_new = thdot + (3.0 * self.g / (2.0 * self.l) * np.sin(th) + 3.0 / (self.m * self.l**2) * u) * self.dt
        thdot_new = float(np.clip(thdot_new, -self.max_speed, self.max_speed))
        th_new = th + thdot_new * self.dt

        self.th, self.thdot = th_new, thdot_new
        self.t += 1
        done = self.t >= self.max_steps
        return self._obs(), float(-cost), done
The interface is kept simple: obs = env.reset() and obs, reward, done = env.step(action) (Gymnasium's step returns five values).
Notation
The same symbols are used throughout the tutorial and the per-chapter pages. \(\log\) always means the natural logarithm.
Symbols in the tutorial
| Symbol | Meaning |
| \(s_t\) | The true state of the environment. For the pendulum, \((\theta, \dot{\theta})\) |
| \(o_t\) | Observation: what the agent actually sees. \([\cos\theta, \sin\theta, \dot\theta]\) in Chapters 6 and 7, and a 64×64 image from Chapter 8 on |
| \(a_t\) | Action. For the pendulum, the torque \(u\) |
| \(r_t\) | Reward: the score received for taking \(a_t\) in \(s_t\) |
| \(z_t\) | Latent variable: a small vector that compresses the observation (from Chapter 8) |
| \(h_t\) | Hidden state: the memory an RNN carries along (from Chapter 9) |
| \(T\), \(H\) | \(T\): length of an episode or sequence. \(H\): length of planning or imagination (horizon) |
| \(p_\theta\) | A distribution defined by a model with parameters \(\theta\) (the World Model) |
| \(q_\phi\) | A distribution defined by an encoder with parameters \(\phi\) (infers the latent variable from the observation) |
| \(\pi_\psi\), \(v_\xi\) | Policy (actor) and value function (critic) |
| \(\mathcal{D}\) | The set of collected data (experience). The replay buffer |
Greek letters
| Symbol | Name | Main meaning |
| \(\theta\) | theta | ① The pendulum's angle ② The parameters of the World Model network. Distinguished by context |
| \(\phi\) | phi | Parameters of the encoder network |
| \(\psi\) | psi | Parameters of the policy (actor) |
| \(\xi\) | xi | Parameters of the value function (critic) network |
| \(\mu\), \(\sigma\) | mu, sigma | Mean and standard deviation (\(\sigma^2\) is the variance). \(\sigma(z)\) with parentheses is the sigmoid function |
| \(\epsilon\) | epsilon | Noise drawn from the standard normal distribution, or a very small number |
| \(\gamma\) | gamma | Discount factor (0 – 1) |
| \(\lambda\) | lambda | Mixing ratio of the λ-return (Chapter 12). Also used for eigenvalues (Chapters 4 and 6) and the number of candidates in CMA-ES (Chapter 10) |
| \(\eta\) | eta | Learning rate. In Chapter 12 also used for the entropy coefficient |
| \(\pi\) | pi | ① The circle constant ② The policy \(\pi(a \mid s)\) ③ \(\pi_k\) is the probability of the \(k\)-th category or mixture component (Chapters 2 and 9) |
| \(\tau\) | tau | ① A trajectory ② The torque applied to the pendulum (Chapter 6) ③ The temperature used when drawing samples (Chapters 9, 10, and 13) |
Common symbols
| Symbol | Meaning |
| \(x_{1:T}\) | Shorthand for \(x_1, x_2, \dots, x_T\) taken together |
| \(\hat{x}\) | \(x\) as predicted or estimated by the model |
| \(\dot{\theta}\), \(\ddot{\theta}\) | The rate of change of \(\theta\) over time (velocity), and acceleration |
| \(x \sim p\) | \(x\) is drawn from the distribution \(p\) (sampling) |
| \(\mathbb{E}_{x \sim p}[f(x)]\) | The average of \(f(x)\) over many draws of \(x\) from \(p\) (Chapter 2) |
| \(\mathcal{N}(\mu, \sigma^2)\) | A Gaussian distribution with mean \(\mu\) and variance \(\sigma^2\) (Chapter 2) |
| \(D_{\mathrm{KL}}(q \,\Vert\, p)\) | KL divergence, which measures how different two distributions are (Chapter 3) |
| \(\nabla_\theta L\) | The gradient vector collecting the derivatives of \(L\) with respect to each component of \(\theta\) (Chapter 4) |
| \(\operatorname*{arg\,max}_x f(x)\) | The \(x\) that makes \(f(x)\) largest |
| \(a \odot b\) | Element-wise product |
| \(\operatorname{sg}(x)\) | Stop-gradient. The value is used as is, but no gradient flows back through this part (Chapter 12) |
Not covered
- Distributed training of large models and hardware optimization.
- Practical deployment issues such as applying models to real robots and safety verification.
- Implementing very large video World Models such as Sora and Genie. Chapter 13 explains only their principles and where they fit. Their foundations, latent spaces and autoregressive prediction, are covered in the earlier chapters, and diffusion models in a small exercise in Chapter 13.
See also
- World Models
- Recurrent World Models Facilitate Policy Evolution - The Ha & Schmidhuber paper covered in Chapter 10
- Reinforcement learning
- Deep learning
- PyTorch
- VAE
- Physical AI