RF-DETR:Tutorial
lastmod 2026-11-18created 2026-11-181 edits
RF-DETR Tutorial is a 16-chapter (00 – 15) guide written so that a machine learning beginner can work through the real-time object detector RF-DETR from start to finish on their own. It starts from the question "How do you write a box down as numbers?", builds up scoring, losses, attention, and the DETR lineage one step at a time, and ends by implementing small-scale versions of RF-DETR's architecture, training, architecture search, and segmentation in PyTorch, running them, and then fitting the real released model to your own data. This page is a map of the tutorial; each chapter has its own summary page.
- Original: 00. Getting Started - RF-DETR Tutorial (pages.unwiki.net)
- Setting: all hands-on work from Chapter 2 through Chapter 13 uses a single small detection dataset called Shape World (96×96 images, each with 1 – 4 circles, rectangles, and triangles). Chapter 14 renders the same scenes at 192 pixels and fine-tunes the real RF-DETR.
- Formulas are worked through line by line, and values computed by hand are checked against the same values computed in code. All outputs, plots, and figures in the text are exactly what the actually executed code produced.
What this tutorial promises
Introductions to RF-DETR usually start with a single line: "an LW-DETR decoder on a DINOv2 backbone, plus NAS." For a beginner, every word in that line is a wall. This tutorial gets over that wall by building up from the bottom, and it makes four promises.
- No skipping. When a formula appears, it is unpacked line by line, with a note beside each line on why it holds. Each formula comes with a hand calculation using actual numbers, and the same value is computed in code to check it.
- Build it yourself. IoU, AP, attention, Hungarian matching, deformable attention, window attention, the losses, NAS, and the segmentation head are all implemented in PyTorch.
- One world, all the way through. Because the data stays the same, you can focus only on what changes in the model, and results can be compared across chapters.
- Report what actually happened. In small experiments, a paper's technique sometimes does not help as much as expected. Such results are reported without cherry-picking or polishing, and the tutorial discusses why they might occur. What was observed in this tutorial's mini experiments is always kept separate from what the paper reported on COCO.
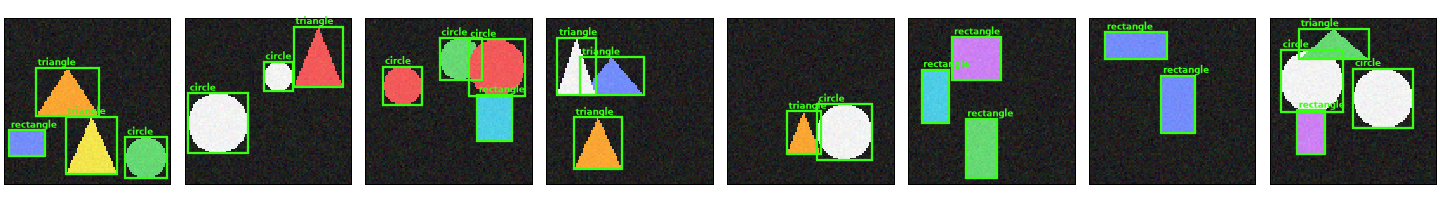
- Figure: Figure 0-1. Eight Shape World images (
ShapesDataset(8, seed=0)) - Each image has two to four circles, rectangles, and triangles in various colors on a dark background, and every shape has a green ground-truth box and class name. The detector's job is to reproduce these green boxes and names from the image alone. Shapes sometimes overlap slightly, and boxes may cross each other.
- Who it is for
- People new to object detection who want to understand the principles rather than how to use YOLO; people who opened a DETR-family paper and got stuck at "Hungarian matching" or "deformable attention"; and people who need to use RF-DETR on their own data and want to understand what each setting means.
- What you get by reading to the end
- The ability to read the tables in detection papers (AP, AP50, latency) from their definitions. An explanation of what changed, and why, from DETR → Deformable DETR → LW-DETR → RF-DETR. An understanding of RF-DETR's forward pass and loss down to the tensor shapes, plus a mini implementation you wrote yourself. The ability to run inference, fine-tuning, and export with the
rfdetrpackage while knowing what happens inside.
RF-DETR in one sentence
- Key idea
- RF-DETR is a real-time object detector that takes an image and outputs "what is where" as a set of boxes, classes, and scores. It places a lightweight LW-DETR-style decoder on a ViT backbone pretrained with DINOv2, and uses weight-sharing NAS to extract many models, from fast to accurate, from a single training run.
Written as a formula, a detector does the following: one image goes in and \(N\) predictions come out.
\(\text{image} \;\xrightarrow{\ \text{detector}\ }\; \{(b_i,\ c_i,\ s_i)\}_{i=1}^{N}\)
\(b_i\) is the box of the \(i\)-th prediction (four numbers), \(c_i\) is its class (in Shape World, one of circle, rectangle, or triangle), and \(s_i\) is its score (between 0 and 1; higher means more confident). The braces indicate that the collection is a set, that is, an unordered collection. The storyline of the tutorial is filling in the pieces of this formula one by one.
- How to write a box as numbers and measure how much two boxes overlap (Chapter 2)
- How to score a set of predictions with a single number (Chapter 3)
- The arrow, i.e. the neural network, attention, and backbone inside the detector (Chapters 4 – 6)
- How to train a model to "output a set", and the improvements on that idea (Chapters 7 – 9)
- RF-DETR, which puts all of this together (Chapters 10 – 13)
Contents
Apart from Chapter 00, the tutorial is divided into four stages, and each stage provides the material for the next (Figure 0-2 in the original). Stage 3 completes a "mini RF-DETR" for Shape World, and Stage 4 introduces the real RF-DETR released by Roboflow. First-time readers are advised to read in order.
Each chapter lists both "what you learn" and "what you try in Shape World". AP values in parentheses are from that chapter's main run, on a 0 – 1 scale (Chapter 3 explains how to read them).
Stage 1: Foundations (Chapters 01 – 06)
Measuring, scoring, and seeing. By the end you can explain why RF-DETR came about, compute IoU, GIoU, and AP by hand, derive the gradient of the focal loss, compute one attention step by hand, and count the tokens and parameters of a ViT.
- 01. What Is RF-DETR - What kind of problem object detection is, five things that make detection hard, the lineage from two-stage and one-stage detectors to DETR, "real time" and the Pareto curve, and RF-DETR's motivation, architecture, contributions, and numbers. Readable without formulas; no code.
- 02. Boxes and IoU - Two box representations, IoU and GIoU, box regression losses (L1 and GIoU) and their gradients. Implements IoU and GIoU and checks them against hand calculations, then fits a single box to the ground truth with gradient descent.
- 03. Scoring a Detector: AP and mAP - True positives, false positives, and false negatives, precision and recall, the PR curve, COCO-style AP, and NMS. Uses "fake detectors" built by perturbing the ground truth to see what AP responds to.
- 04. Deep Learning Basics and Classification Loss - A quick tour of neural networks, backpropagation, AdamW, normalization layers, and convolution, followed by full derivations of the sigmoid, BCE, focal loss, and prior-probability bias initialization. Trains a classification problem with only about 0.6% positives under three settings and compares them.
- 05. Attention and Transformer - Hand-computing attention with queries, keys, and values; each symbol in \(\operatorname{softmax}(QK^\top/\sqrt{d_k})\,V\); multi-head attention; positional encoding; and the Transformer layer. A learned query finds shapes of a given color with a single cross-attention layer.
- 06. Vision Transformer and DINOv2 - ViT, which cuts an image into patches; interpolating position embeddings; and DINO and DINOv2, which learn without labels. Trains a MiniViT with supervised learning and runs self-distillation with a mini DINO.
Stage 2: The DETR Lineage (Chapters 07 – 09)
From set prediction to real time. By the end you can solve Hungarian matching on a cost matrix by hand, train an NMS-free detector from scratch, read a single sampling point of deformable attention by hand, and say what each LW-DETR component trims away.
- 07. DETR: Detection as Set Prediction - Viewing detection as set prediction, Hungarian matching, the set loss, object queries, and auxiliary losses. Trains a mini DETR from scratch (validation AP 0.8375) and checks whether NMS is really unnecessary.
- 08. Deformable DETR: Looking Only Where Needed - Bilinear interpolation, deformable attention, iterative box refinement, and two-stage query selection. Trains a mini Deformable DETR under the same conditions as Chapter 7 (validation AP 0.8982) and compares the two.
- 09. Real-Time DETR: RT-DETR and LW-DETR - The ideas behind RT-DETR, and LW-DETR's components: window attention and window-major layout, the C2f projector, IA-BCE, Group DETR, and box reparameterization. Implements each component and checks it against the formulas and hand calculations (no training).
Stage 3: RF-DETR (Chapters 10 – 13)
Completing the mini RF-DETR. By the end you can follow the tensor shapes from one image to 300 boxes, compute the total loss by hand, turn the knobs on a model trained once to extract many models, and attach a segmentation head to a detector.
- 10. RF-DETR Architecture - The eight steps of RF-DETR's forward pass and their tensor shapes, and a component-by-component count of its 30,467,298 parameters (RF-DETR Nano). Assembles
MiniRFDETRfrom the components built through Chapter 9 and sets it side by side with the real Nano. - 11. Training RF-DETR - The total loss, training without a scheduler, gradient clipping, EMA, layer-wise learning rate decay, and pretraining. Trains the mini RF-DETR for 60 epochs (validation AP of the EMA model: 0.9347) and reads five ablation experiments.
- 12. Weight-Sharing NAS - Pareto optimality, weight-sharing NAS, the five knobs (resolution, patch size, number of windows, number of decoder layers, number of queries), and how to measure latency correctly. Extracts 408 configurations from a model trained once and plots the Pareto curve.
- 13. RF-DETR-Seg: Instance Segmentation - Masks made from the dot product of query embeddings and pixel embeddings, mask BCE, and Dice loss. Attaches a segmentation head to the Chapter 11 model and trains it for 30 epochs (mask AP 0.8766).
Stage 4: In Practice (Chapters 14 – 15)
The real model on your own data. By the end you can run inference with the released RF-DETR, convert your data to COCO format and fine-tune on it, export to ONNX and measure latency, and know where to look first when training does not work.
- 14. In Practice: The rfdetr Package - Inference, COCO-format data, fine-tuning, evaluation, and ONNX export with the
rfdetrpackage. Fine-tunes RF-DETR Nano on Shape World for 5 epochs (test-set AP 0.9830), exports it to ONNX, and times it. - 15. Appendix: Debugging, Glossary, Next Steps - A checklist for when you are stuck, a formula collection, a glossary, and papers for further reading. A reference for looking up the section you need rather than reading from the start.
Do not rank the AP values in the list above against each other. The values in Chapters 7, 8, and 11 were measured on the same validation set (500 images), but the model sizes and training settings differ, and Chapter 14 uses a different image size (192 pixels) and evaluation set. Conclusions like "technique X is this much better" can only come from comparisons under matched conditions. Also, all of these values come from Shape World, so they must not be read alongside the values the paper reports on COCO.
How to read
You can choose how deeply to read depending on your goal. Whichever path you take, always look at each chapter's "Key idea" boxes and figures.
| Path | For | How to read |
| A. Intuition path | When you want to grasp the concepts quickly | Read only each chapter's introduction, figures, key-idea boxes, and "Chapter summary", and look only at the result lines of the worked-solution boxes. Do not run the code. |
| B. Math path | When you want to be able to read the papers | Read every chapter in order, copying each worked-solution box onto paper line by line. Try the review questions. |
| C. Implementation path | When you want to build it yourself | In addition to B, run each chapter's hands-on files yourself and compare the results with the outputs in the text. Change the numbers and run them again. |
Shortcuts when you are in a hurry
| Goal | Chapters to read (in order) | What you can skip |
| You need to use it on your own data right away | 01 → first part of 02 (two box representations, IoU) → first part of 03 (what AP means) → 14 | All derivations. When Chapter 14 points out that "this setting is X from Chapter N", go and read just that section. |
| You need to read the RF-DETR paper | 01 → 05 → 07 → 08 → 09 → 10 → 11 → 12 | Look up Chapters 2 – 4 and 6 as needed. Chapter 13 only if you are interested in segmentation. |
| You only need to know what DETR is | 01 → 02 → 05 → 07 | From Chapter 8 on, the story is about making DETR faster and lighter. |
| You are only curious about the NAS part | 01 → resolution and patch size sections of 06 → 10 → 12 | Chapter 12 reuses the Chapter 10 model and the Chapter 11 training code, but if you are only reading, the results of Chapter 11 are enough. |
If you get stuck on a formula, first read the explanation for that line (the text after "↳"), and if a concept from an earlier chapter is hazy, follow the chapter link. All terms are collected in the glossary in the Chapter 15 appendix.
What you need
Background knowledge
- Python basics: enough to read variables, functions,
forloops, lists and dictionaries, and classes. - High school math: functions, exponents and logarithms, graphs, simple derivatives ("slope"), and the coordinate plane. If you have forgotten them, they are explained again when needed.
- You do not need to know the following in advance. Matrix and vector multiplication is covered together with shapes in Chapter 5; probability, only as much as needed to derive BCE in Chapter 4; deep learning and PyTorch in Chapter 4, which summarizes the components the later chapters use; convolution in Chapter 4; and turning images into tokens in Chapter 6.
- If you are completely new to deep learning and want a slower pace for hand-computed backpropagation or the derivations of probability and KL divergence, the deep learning basics chapter of the World Model tutorial, written in the same style, can help. You can follow this tutorial without reading it.
Computer and GPU
- Windows, macOS, or Linux all work. The hands-on code automatically picks a device in the order cuda → mps → cpu.
- Chapters 2 and 3 do not use a GPU and finish in a few seconds to a minute on a CPU. Chapters 9 and 10 have no training and also finish quickly.
- The chapters that train models (Chapters 4 – 8 and 11 – 14) benefit from a GPU. All numbers in the tutorial were produced on a single laptop GPU with 8 GB of memory, and a single main run takes at most around 30 minutes. Times for main runs on a CPU alone were not measured.
- Without a GPU, use
--quickjust to check that the code runs and then read the outputs and figures in the text, or use a free GPU environment such as Google Colab. - Part of Chapter 14 (the pretrained weights for
rfdetr) and the optional exercise in Chapter 6 (DINOv2 weights, about 88 MB) download files on the first run, so an internet connection is required.
Installation
Python 3.10 or later is required. $ marks a line you type in, so do not type the $ itself.
$ python --version              # Python 3.10 이상인지 확인 (macOS · Linux 는 python3)
$ mkdir rf-detr && cd rf-detr    # 실습 폴더. 실습 파일을 모두 여기에 둡니다
$ python -m venv .venv           # 이 폴더 전용 Python 환경 만들기
$ source .venv/bin/activate      # Windows 는: .venv\Scripts\activate
$ pip install -r requirements.txt   # torch · numpy · matplotlib · scipy
venv (a virtual environment) creates a dedicated Python environment just for these exercises, so packages installed in it do not mix with other projects. requirements.txt lists the four packages used in Chapters 2 – 13 along with their minimum versions.
| Package | Minimum version | Used for |
| | 2.2 | All models and training |
| | 1.26 | Drawing Shape World images, numerical computation |
| | 3.8 | Figures in the text |
| | 1.11 | Solving Hungarian matching ( |
To use an NVIDIA GPU, install the CUDA build of torch before installing requirements.txt, using the command shown after you select your environment in the PyTorch installation guide. torchvision is not used in Chapters 2 – 13, because the goal is to implement the principles yourself.
If a version number appears, the installation worked. The second value is True if an NVIDIA GPU is available and False otherwise; either way, you can start the exercises.
Only Chapter 14 needs additional packages, and you can install them when you get there.
-
rfdetr: the RF-DETR package released by Roboflow. The tutorial was verified with version 1.12.1. -
[train]: the group of packages needed fortrain()andevaluate(). -
[onnx]: the packages needed to export to ONNX and run inference with the exported file (onnx,onnxruntime). - Optional: the optional Chapter 6 exercise
ch06_dinov2_features.pyrequirestransformers(pip install transformers). Ifrfdetris installed, the Chapter 10 and 13 hands-on files also run the part that compares against the real RF-DETR Nano; if not, they skip only that part.
Hands-on code
Each chapter's code is in the original's code/ folder (download files such as rf_shapes.py from under https://pages.unwiki.net/rf-detr/code/). The code boxes in the original text pull in parts of those files verbatim, so the text and the files never diverge. There are two shared files, requirements.txt (the list of required packages) and rf_shapes.py (the Shape World data), and the hands-on files for Chapters 2 – 14 import rf_shapes.py either directly or through an earlier chapter's file.
Put all downloaded files in the same folder and run them from that folder, because later chapters' files import functions and classes from earlier chapters' files (for example, the Chapter 11 training code imports the files from Chapters 2, 3, 7, 8, 9, and 10). Figures are saved to figures/ under that folder, and checkpoints (*.pt) and logs (*.json) are saved in the folder you ran the file from.
First, run only the Shape World file to verify the installation.
$ python rf_shapes.py
그림 (3, 96, 96) torch.float32 값 범위 0.0 1.0
박스 (cx, cy, w, h) [[0.14, 0.753, 0.216, 0.151], [0.528, 0.768, 0.31, 0.344], [0.384, 0.448, 0.382, 0.292], [0.854, 0.843, 0.247, 0.247]]
클래스 [1, 2, 2, 0] → ['사각형', '삼각형', '삼각형', '원']
마스크 (4, 96, 96) torch.bool
그림마다의 객체 수 [4, 3, 4, 3, 2, 3, 2, 4]
shapes_world.png 저장
It finishes in a little over a second and creates shapes_world.png in the folder you ran it from. Figure 0-1 is exactly this image. The four boxes in the output belong to the leftmost image in Figure 0-1: the first box, [0.14, 0.753, 0.216, 0.151], is the blue rectangle at the bottom left, and the last box is the green circle at the bottom right.
Hands-on files and run times
Times were measured on the computer used to write the tutorial (a single laptop GPU with 8 GB of memory). Most times marked "GPU" were measured while the GPU was shared with other work and may be shorter on a GPU used exclusively, so treat them only as rough magnitudes.
| File | Chapter | Time for the main run | | Output |
| | 00 | A little over 1 s | - | |
| | 02 | CPU 8 – 15 s | About 3 s | 5 figures |
| | 03 | CPU a little over 1 min | 10 – 20 s | 5 figures |
| | 04 | GPU 5 min 40 s | About 20 s | 6 figures |
| | 05 | GPU about 2 min | CPU under 40 s | 6 figures |
| | 06 | GPU 10 min 30 s | GPU about 12 s / CPU about 30 s | 6 figures |
| | 06 | GPU about 1 min 30 s | Available (not timed) | Figure |
| | 07 | GPU about 15 min | CPU about 15 s | 5 figures |
| | 08 | GPU about 27 min | CPU about 30 s | 9 figures |
| | 09 | GPU about 32 s | CPU about 7 s | 5 figures |
| | 10 | GPU about 35 s | CPU about 15 s | 3 figures |
| | 11 | GPU about 17 min | CPU about 20 s | Figures |
| | 12 | GPU about 18 min | CPU about 20 s | Figures |
| | 13 | GPU about 10 min | CPU about 30 s | Figures |
| | 14 | CPU about 15 s | A little over 1 s | COCO-format folder |
| | 14 | GPU about 30 min | About 35 s (inference only, no training) | Training output folders |
| | 14 | GPU + CPU about 5 min | 1 – 2 min | ONNX files ( |
Most files can be run starting from any chapter, but the following four use result files left by earlier runs.
-
ch08_deformable.py: ifch07_history.jsonis in the same folder, it overlays the Chapter 7 training curve. It still runs without it. -
ch12_nas.py --searchand--finetune: requirech12_nas.pt, which is created by runningpython ch12_nas.pyfirst. -
ch13_seg.py: starts from Chapter 11'sch11_rfdetr.pt. Without it, it starts from random initialization and produces results different from the text. - Chapter 14: run
ch14_make_coco.py→ch14_finetune.py→ch14_export.pyin that order.
Quick-check mode
Every per-chapter hands-on file (ch02 – ch14) has a --quick option. It is a scaled-down version with fewer images, epochs, and iterations that finishes in a few seconds to two minutes.
- Purpose: to check that the installation is correct and that the code runs to the end. No GPU needed.
- Caution: the numbers and figures produced by
--quickare meaningless, because the model is barely trained. To compare with the values in the text, do a main run. - Arguments used alongside it:
--fig-dir(folder to save figures in, defaultfigures) and--seed(random seed, default 0). - Because the seed is fixed, the same computer gives the same results. However, a different GPU model or PyTorch version can change the third or fourth decimal place, and the longer the training, the more that difference accumulates. If your AP is at a similar level to the text, the run worked.
Shape World
Training RF-DETR on COCO, a real detection dataset, takes many GPUs, but the mini models for Shape World train in ten-odd minutes on a single laptop GPU. Small as it is, it still contains the skeleton of the detection problem: the number of objects varies from image to image, sizes and positions vary, and objects can overlap.
- Image: a 96×96-pixel RGB image. The tensor shape is
(3, 96, 96)and values are in 0 – 1. The background is dark gray with a little noise. - Objects: 1 – 4 per image. Each is 0.14 – 0.42 times the side of the image and never extends outside it.
- Classes: three. Index 0 is circle, 1 is rectangle, and 2 is triangle.
- Color: chosen at random from eight colors. Color is unrelated to class, so the model has to tell classes apart by shape, not by color.
- Overlap: slight overlap is allowed, and shapes drawn later cover those drawn earlier. However, objects that are almost entirely hidden by other shapes are not generated.
- Ground truth: a box
(cx, cy, w, h)and a class index for each object. Chapter 13 also uses masks that mark the pixels each object occupies.
CLASS_NAMES = ["circle", "rectangle", "triangle"]  # 클래스 번호 0, 1, 2
CLASS_NAMES_KO = ["원", "사각형", "삼각형"]
NUM_CLASSES = len(CLASS_NAMES)
The function sample_scene, which samples one scene, draws a class, a size, and a center in turn, and draws again if the new shape overlaps too much with shapes already placed (IoU above 0.2, or more than 35% of the smaller shape covered). Scenes are recorded in coordinates normalized to 0 – 1, so the same scene can be rendered at 96 pixels or larger. Chapters 2 – 13 use 96 pixels by default, the NAS in Chapter 12 renders at varying resolutions, and Chapter 14 renders at 192 pixels. The hands-on files do not sample scenes one at a time; they build them all at once with ShapesDataset.
There are three conventions to remember.
- Ground-truth format: the ground truth for one image is a single dictionary.
"boxes"holds normalized(cx, cy, w, h)values with shape(number of objects, 4), and"labels"holds class indices with shape(number of objects,). - Batches: images are stacked into a single tensor
(B, 3, 96, 96), but ground truths cannot be stacked because the number of objects differs per image, so they are kept as a list (collate). The detection difficulty that "the count differs from image to image" shows up as early as the data-loading step. - Seeds: the same
seedalways produces the same data.seed=0is used for training,seed=1for validation, andseed=2for testing.
def collate(batch):
    """그림은 한 텐서로 쌓고, 정답은 그림마다 객체 수가 달라 목록으로 둔다."""
    images = torch.stack([image for image, _ in batch])
    targets = [target for _, target in batch]
    return images, targets
Shape World is a toy for getting a hands-on feel for the principles. Real photos have texture, lighting, occlusion, and tens to hundreds of classes, and objects are much smaller or more numerous. A technique having no effect in Shape World does not mean it has no effect on COCO, and vice versa. Performance on real data is given separately, as the values reported in the papers along with their sources.
Notation
The same symbols and terms are used throughout the tutorial and the per-chapter pages.
Two ways to write a box
There are two ways to write the same box with four numbers, and the tutorial switches between them depending on the use. They are covered in detail in Chapter 2.
| Name | Symbol | Name in code | Meaning | Main uses |
| Center representation | \((c_x, c_y, w, h)\) | | Horizontal and vertical coordinates of the center, width, height | Ground truth in the data, model outputs, L1 loss |
| Corner representation | \((x_0, y_0, x_1, y_1)\) | | Coordinates of the top-left and bottom-right corners | Computing area, IoU, and GIoU; drawing on images |
- Normalized coordinates: unless stated otherwise, coordinates are values from 0 to 1, obtained by dividing by the image width and height. To convert to pixels in a 96-pixel image, multiply by 96. For example, the left edge of the box \((0.5,\ 0.5,\ 0.25,\ 0.5)\) is \(x_0 = c_x - w/2 = 0.5 - 0.125 = 0.375\), i.e. \(0.375 \times 96 = 36\) pixels, and the right edge is \(x_1 = c_x + w/2 = 0.625\), i.e. 60 pixels. The 24-pixel difference between the two edges equals the width, \(0.25 \times 96 = 24\) pixels. The box's area of \(24 \times 48 = 1152\) pixels is 12.5% of the image's 9216 pixels, which matches \(0.25 \times 0.5 = 0.125\) computed directly in normalized coordinates. Area in normalized coordinates is "the fraction of the image covered".
- Origin and direction: the origin is the top-left corner of the image; the horizontal coordinate increases to the right and the vertical coordinate increases downward. The vertical direction is the opposite of the coordinate plane from math class.
- Indices start at 0: indices in code, such as class and layer indices, count from 0. When the text counts from 1, it says so.
- COCO format is different again: the COCO format in Chapter 14 is
[x, y, w, h]in pixels, and the first two numbers are the top-left corner, not the center.
Tensor shapes and numbers
- Tensor shapes: the length of each axis is written in parentheses, as in
(B, N, D).Bis the batch size (the number of images fed in at once),Nis the number of tokens or queries, andDis the vector dimension. Wherever the shape changes, the new shape is stated. - AP scale: the tutorial's experiment outputs write AP on a 0 – 1 scale, as in 0.9347. Papers multiply this by 100 and write it as, for example, 48.0. "48.0 AP" means 0.480.
- Distinguishing sources: numbers are labeled to distinguish "in this tutorial's experiments" from "in the paper (Table N)". When the paper and the released code differ, both are given side by side.
- Logarithms: \(\log\) in formulas always means the natural logarithm.
Greek letters
The "Details" column gives the chapter where the letter is first used with that meaning.
| Symbol | Name | Main meaning | Details |
| \(\alpha\) | alpha | Balancing weight of the focal loss (0.25). From Chapter 9 on, also used as the exponent in IA-BCE | Chapter 4 |
| \(\gamma\) | gamma | Exponent in the focal loss that sets how strongly easy cells are down-weighted (2) | Chapter 4 |
| \(\eta\) | eta | Learning rate (how much to adjust in one step) | Chapter 4 |
| \(\theta\) | theta | All parameters of a neural network (weights and biases) | Chapter 4 |
| \(\sigma(z)\) | sigma | The sigmoid function. Maps a real number \(z\) to a value between 0 and 1. In Chapter 7 only, \(\sigma\) denotes a matching assignment | Chapter 4 |
| \(\lambda\) | lambda | Coefficient for weighting the terms of a loss. Also used for the strength of weight decay (Chapter 4) and the layer-wise learning rate decay rate (Chapter 11) | Chapter 2 |
| \(\tau\) | tau | IoU threshold. Also used for the softmax temperature (Chapter 6), how quickly the EMA decay ramps up (Chapter 11), and the score threshold (Chapter 14) | Chapter 3 |
| \(\delta\) | delta | Offsets output by the box head: how far to shift the reference box and how much to scale it | Chapter 9 |
| \(\textstyle\sum\) | sigma (uppercase) | Sum over the range written below and above it | - |
| \(\textstyle\prod\) | pi (uppercase) | Product over the range written below and above it | - |
Common symbols
| Symbol | Meaning | Details |
| \(b\), \(\hat{b}\) | \(b\) is a ground-truth box, and \(\hat{b}\), with a hat (^), is a box predicted by the model. A hat always marks a "predicted value" | Chapter 2 |
| \(\operatorname{IoU}(\hat{b}, b)\) | Area of the intersection ÷ area of the union of two boxes. 0 (no overlap) – 1 (identical) | Chapter 2 |
| \(\operatorname{GIoU}(\hat{b}, b)\) | IoU modified so that it also indicates how far apart non-overlapping boxes are. −1 – 1 | Chapter 2 |
| \(\mathrm{AP}\) | Average precision. The single number on a detector's report card | Chapter 3 |
| \(z\), \(p\) | \(z\) is a logit (the real number before the sigmoid), and \(p = \sigma(z)\) is that value converted to a probability | Chapter 4 |
| \(\theta \leftarrow \theta - \eta \nabla_\theta L\) | One step of gradient descent. The arrow means "compute the right-hand side and store it in the left", and \(\nabla_\theta L\) is the gradient of the loss \(L\) | Chapter 4 |
| \(\frac{\partial L}{\partial z}\) | The rate at which \(L\) changes when only \(z\) is changed slightly and everything else is held fixed (partial derivative) | Chapter 4 |
| \(\operatorname{softmax}(QK^\top / \sqrt{d_k})\,V\) | One attention step. \(Q\), \(K\), and \(V\) are matrices with the queries, keys, and values stacked as rows, and \(^\top\) is the transpose, which swaps rows and columns | Chapter 5 |
| \(\operatorname*{arg\,min}\), \(\operatorname*{arg\,max}\) | The input that makes the following value smallest (largest). Not the minimum itself, but the input that achieves it. Chapter 7's matching writes "the assignment with the lowest cost" this way | Chapter 7 |
| \(\varnothing\) | The "no object" class. The answer a query should give when it is not responsible for any object | Chapter 7 |
| \(\operatorname{sg}(\hat{b})\) | Stop-gradient. The value is used as is, but no gradient flows back through this part | Chapter 8 |
| \(\approx\) | Approximately equal | - |
| \(:=\) | Defines the name on the left as the expression on the right | - |
Some letters mean different things in different chapters. This is because the tutorial follows widely used conventions; where a letter has to carry two meanings within one chapter, the text says so.
- \(p\): a probability in the losses from Chapter 4 on; the patch size (in pixels) in the architecture discussions of Chapters 6, 10, and 12.
- \(N\): the number of tokens in Chapters 5, 6, and 9; the number of object queries in the decoder discussions from Chapter 7 on.
- \(K\): the number of classes in Chapters 4, 7, and 11; the number of sampling points in deformable attention in Chapters 8 and 10.
- \(L\): the loss in Chapter 4, and also the number of layers from Chapter 6 on. From Chapter 7 on, the loss is mostly written as \(\mathcal{L}\).
Terminology
Korean writing on object detection often transliterates English words by sound, so the same thing tends to go by two or three names. The tutorial, which is written in Korean, follows these principles.
- Use only one name per concept.
- Choose a Korean word that conveys the meaning, and give the original English term alongside it once, on first use.
- Write the names of models, papers, and datasets in English as is: DETR, Deformable DETR, LW-DETR, RF-DETR, DINOv2, ViT, Transformer, and COCO.
- Write names from code in code font as is. Identifiers from the official implementation, such as
num_queriesandclass_embed, are not changed.
| English | Term used in the (Korean) tutorial | Note |
| bounding box | 박스 (loanword for "box") | Also called 경계 상자 ("boundary box") |
| ground truth | 정답 (literally "correct answer") | 정답 박스 (ground-truth box), 정답 클래스 (ground-truth class) |
| score, confidence | 점수 ("score") | Also called 신뢰도 ("confidence") |
| threshold | 문턱값 ("threshold value") | IoU 문턱값 (IoU threshold), 점수 문턱값 (score threshold) |
| backbone / projector / head | 백본 / 프로젝터 / 머리 (loanwords for the first two; 머리 is the native word for "head") | 분류 머리 (classification head), 박스 머리 (box head), 분할 머리 (segmentation head). Multi-head attention is 다중 머리 어텐션 |
| query / key / value | 질의 / 열쇠 / 값 (native Korean words) | Object query is 객체 질의 |
| self- / cross-attention | 자기 어텐션 / 교차 어텐션 | |
| deformable attention | 변형 어텐션 | Reference point is 기준점, sampling point is 표본점 |
| Hungarian matching | 헝가리안 매칭 | Cost is 비용, assignment is 배정 |
| weight / parameter | 가중치 / 매개변수 | Only hyperparameter uses the loanword 하이퍼파라미터 |
| gradient | 기울기 (literally "slope") | Stop-gradient is 기울기 차단 |
| sample / noise | 표본 / 잡음 | Sampling is 표본 추출, or informally 뽑기 ("drawing") |
| pre-training / fine-tuning | 사전 학습 / 미세 조정 | |
| latency / throughput | 지연 시간 / 처리량 | |
| layer / shape / hidden | 층 / 모양 / 은닉 | A tensor's shape is its 모양 ("form") |
| knob (NAS) | 손잡이 (literally "handle") | Resolution, patch size, number of windows, number of decoder layers, number of queries |
The Korean text also follows one spacing convention: a particle that follows an English word, number, or symbol is separated from it by a space ("DETR 은", "IoU 가", "0.5 를"), so that you can see at a glance where the particle begins.
Not covered
- Actual training on large datasets such as COCO and Objects365. That scale needs many GPUs, so the tutorial does not do it and instead reads the values reported in the papers, along with their sources.
- The internals of other detectors such as the YOLO family and D-FINE. Chapters 1 and 9 touch on them only as much as needed to compare them with RF-DETR.
- Building TensorRT engines and reproducing latency on an NVIDIA T4. Chapter 12 explains the paper's measurement procedure, and Chapter 14 exports as far as ONNX and measures on the tutorial's computer.
- Open-vocabulary detection, keypoint detection, and tracking in video. Chapter 1 covers only how they relate to RF-DETR.
- The practicalities of collecting and labeling data. Chapter 14 starts from converting data that already has ground truth into COCO format.
See also
- RF-DETR
- RF-DETR:Review
- Object detection
- DINOv2
- Vision Transformer
- Transformer
- Instance segmentation
- Roboflow
- WorldModels:Tutorial - A World Model tutorial written in the same style