RF-DETR:Tutorial:01-WhatIsRFDETR
lastmod 2026-11-18created 2026-11-182 edits
What Is RF-DETR is Chapter 1 of the RF-DETR tutorial. It starts from the exact question that object detection asks, namely "what is where" in an image. It then follows how detectors have changed over the past decade or so, from two-stage detectors to one-stage detectors to DETR to real-time DETRs, and finally gives a big-picture view, without equations, of where RF-DETR (released in 2025) stands in that lineage and what it changed and why. The arithmetic amounts to a few divisions. The concepts that are only named here (IoU, AP, attention, Hungarian matching, deformable attention, weight-sharing NAS) are filled in one at a time, with hand calculations and code, from Chapter 2 onward.
- Original: 01. What Is RF-DETR
- Practice code: This chapter has no code of its own. The Shape World data is generated by
code/rf_shapes.py(about 50 minutes to read, difficulty ★☆☆☆☆). - Previous: Tutorial hub / Next: 02. Boxes and IoU
Finding objects in an image: object detection
A self-driving car's camera needs to know whether there is a pedestrian ahead and, if so, where. An inspection machine in a factory has to count how many defective solder joints are on a circuit board, and the cameras in a checkout-free store need to know what item a customer has picked up. In all three cases, a one-line answer to "what is this a picture of?" is not enough. For each object in the image, the system must answer what it is and where it is.
This problem is called object detection, and a model that solves it is called a detector. An "object" is a single, separately countable thing in the image.
- Key point
- Object detection takes a single image and, for each object in it, answers both "where is it (a box)" and "what is it (a class)". The number of objects is not given in advance; the detector has to work that out too.
The stage for this tutorial: Shape World
Real photos are too complex to follow the principles by hand. So from start to finish, the tutorial uses a small stage called Shape World. Each image is a dark 96×96-pixel picture with one to four circles, rectangles, and triangles placed on it, with position, size, and color randomized per image (the generator is rf_shapes.py, introduced in Chapter 0).
- Figure: Figure 1-1. Eight Shape World images and their ground truth - One to four circles, rectangles, and triangles on a dark background, each with a green ground-truth box and its English class name above it (circle, rectangle, triangle).
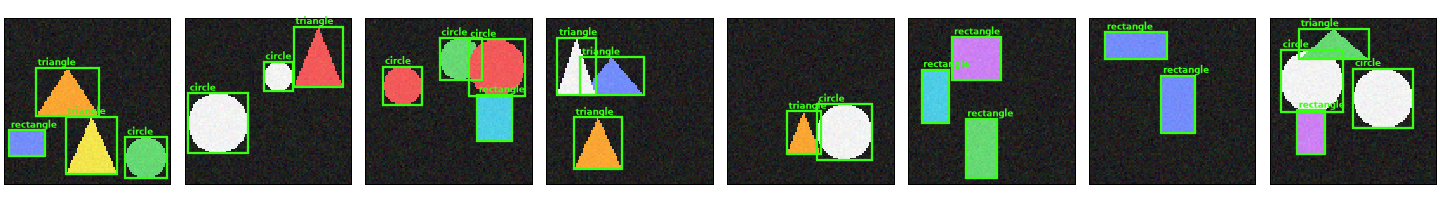
Three things in this figure are worth noticing.
- The number of objects varies by image. From left to right: 4, 3, 4, 3, 2, 3, 2, and 4.
- Sizes and positions vary. Even among circles, the large and small circles in the second image differ in diameter by a factor of two.
- Shapes sometimes overlap slightly. As in the first and eighth images, one shape can partly hide another.
Shape World looks like a toy, but it has the same difficulties as real object detection. Through Chapter 14, the tutorial builds detectors from scratch on this stage, and in Chapter 14 it moves on to real photos and the real RF-DETR.
Classification, detection, and instance segmentation
Image understanding problems split into several levels depending on how detailed the answer must be. Figure 1-2 of the original tutorial uses the second image of Figure 1-1 (one triangle, two circles) to put the three problems side by side. On the left (image classification), the whole image gets the label "there are circles and a triangle". In the middle (object detection), each object gets its own rectangle, giving three boxes and their classes. On the right (instance segmentation), each object's pixels are painted a different color, distinguishing the two circles as "circle 1" and "circle 2". The answers get more detailed from left to right. The middle one is the subject of this tutorial, and the right one is covered in Chapter 13.
- Image classification: Puts a label on the whole image: "This image contains a circle and a triangle." It does not say where things are or how many there are. The fact that there are two circles does not appear in the answer.
- Object detection: For each object, gives the type and a rectangle that tightly encloses the object. This rectangle is called a box (bounding box; see Chapter 2 for details). If there are two circles, there are two boxes.
- Instance segmentation: Instead of a box, it precisely paints the pixels each object occupies. The painted region is called a mask. An "instance" is an individual entity within a type. The two circles in the image share a type but are different instances, so they must be painted separately (see Chapter 13 for details).
The "type" here is called a class. The list of classes a detector distinguishes is fixed before training. Shape World has three classes: circle (0), rectangle (1), and triangle (2). The COCO dataset, which comes up later, has 80, such as person, car, and dog.
| Problem | What it answers | Answer for Figure 1-2 | Number of answers |
| Image classification | Classes for the whole image | Circle, triangle | Fixed at the number of classes (present / absent) |
| Object detection | Box + class per object | 1 triangle box, 2 circle boxes | Varies by image |
| Instance segmentation | Mask + class per object | 1 triangle mask, 2 circle masks | Varies by image |
A box is coarser than a mask: about half the pixels inside a box around a triangle are not part of the triangle. Even so, a box can be written as four numbers, which makes it easy to work with, and "there is something there" is enough information for most applications. That is why object detection is one of the most widely used problems in computer vision.
Input and output: a detector outputs a set
Written out precisely, this is what goes into a detector and what comes out.
- Input: One image. To a computer, an image is an array of numbers. A Shape World image is three stacked 96×96 arrays for red, green, and blue, that is, 27,648 numbers of shape
(3, 96, 96). - Output: A set of predictions. Each prediction consists of three things: (box, class, score).
In symbols, this is as follows. It is almost the only formula used in this chapter.
\(\text{출력} = \{(b_1, c_1, s_1),\; (b_2, c_2, s_2),\; \dots,\; (b_N, c_N, s_N)\}\)
- The braces \(\{\;\}\) denote a set (the left-hand side is the output). The order in which elements are listed in a set has no meaning. Whether the circle or the triangle is written first, the answer is the same.
- \(N\) is the number of predictions, and the subscript \(i\) is a label meaning "the \(i\)-th prediction" (\(i = 1, 2, \dots, N\)).
- \(b_i\) is the box of the \(i\)-th prediction (b for box). It is written as four numbers \(b_i = (c_x, c_y, w, h)\), where \(c_x, c_y\) are the horizontal and vertical coordinates of the box center, \(w\) is the width, and \(h\) is the height. In this tutorial, all four numbers are divided by the image size so they fall between 0 and 1 (normalization). Chapter 2 explains why.
- \(c_i\) is the class index (c for class). In Shape World it is one of 0 (circle), 1 (rectangle), or 2 (triangle).
- \(s_i\) is the score (s for score). It expresses, as a number between 0 and 1, "how confident the detector is that this prediction is correct". It is also called confidence, and values closer to 1 mean higher confidence.
The ground truth for the image in Figure 1-2 (the second image of Figure 1-1) is the following three rows. They are the actual values produced by rf_shapes.py, rounded to two decimal places.
| Object | Class | Box \((c_x, c_y, w, h)\) | Reading |
| Triangle | 2 | (0.80, 0.24, 0.30, 0.36) | Upper right. Width is 30% of the image, height 36% |
| Large circle | 0 | (0.20, 0.64, 0.36, 0.36) | Lower left. A circle, so width = height |
| Small circle | 0 | (0.56, 0.35, 0.18, 0.18) | Upper middle. Half the size of the large circle |
Multiplying the normalized values by the image size of 96 gives pixel units. The large circle's width is \(0.36 \times 96 \approx 35\) pixels, and its center's horizontal coordinate is \(0.20 \times 96 \approx 19\) pixels. This matches the second image of Figure 1-1, where the large circle almost touches the left edge (center 19 − radius about 17.5 ≈ 2 pixels in from the left edge).
The ground truth has no score, because there is nothing to be more or less confident about in the ground truth. Scores are attached only to the detector's predictions. A well-trained detector might output a set like the following for this image (the scores are made up for illustration; you will build actual detector outputs yourself starting in Chapter 7).
{ (박스 (0.80, 0.24, 0.30, 0.36), 클래스 2 삼각형, 점수 0.97),
  (박스 (0.20, 0.64, 0.36, 0.36), 클래스 0 원,     점수 0.95),
  (박스 (0.56, 0.35, 0.18, 0.18), 클래스 0 원,     점수 0.88) }
(Each line in the block above reads: box, class number and name, score.) Users usually apply a threshold to the score, for example drawing only predictions with a score above 0.5. Because there is a score, you can choose between "show me only the sure ones" and "show me anything even slightly suspicious". How this choice changes a detector's results is the subject of Chapter 3.
Why an output of unknown size is hard
Image classification has a fixed-size output. With three classes, it outputs three numbers ("circle score, rectangle score, triangle score") and is done, and there are always three no matter the image. Neural networks are good at this, because a neural network is by nature a function that takes a fixed-size input and produces a fixed-size output (Chapter 4).
Object detection output is different. Some images have two rows of answers and others have four. For real photos, there may be zero rows (nothing there) or dozens (a crowd). This creates two difficulties.
- How to set the output size. A neural network that can only produce fixed-size output has to give an answer of varying length. Nearly every detector so far uses the same trick: output a fixed, generously large number of "candidates" and have most of them answer "nothing here". It is no exaggeration to say that the history of detectors is the history of how these candidates are made and how they are pruned.
- How to grade an unordered answer. A set has no order, so there is no guarantee that the detector's first prediction corresponds to the first row of the ground truth. To train, you first have to decide "which prediction is responsible for which ground-truth object" before you can compute the loss (how wrong it is). This matching problem is the core of DETR in Chapter 7.
As an analogy, a multiple-choice test (classification) has as many answer slots as questions. Object detection is an essay question: "List everything you find in this photo." The answer sheet has 100 slots, and the student fills in only as many as they found and leaves the rest blank. Regardless of the order in which the student wrote things, the grader must first decide which item of the model answer each written answer should be checked against. If the student wrote the same answer twice, it should get credit only once.
Five things that make detection hard
Including the "unknown count" from the previous section, the things that make object detection hard can be summarized as five. Every detector component that appears later was built to solve one of them, so naming them now makes the later chapters much easier to read.
1. The number of objects is unknown
The number of answers varies by image, and the answers have no order. The standard solution is to output a fixed number of candidates and treat most of them as "nothing". What serves as a candidate (region proposals, grid cells, anchors, queries) is what distinguishes the types of detectors.
2. Sizes and positions vary
Objects of the same class can appear anywhere in the image and at any size. Even in Shape World, an object's side ranges from 14% to 42% of the image, a threefold difference. In real photos the difference is much larger: a person right in front of the camera fills the frame, while a distant person is only a few pixels. Seeing small objects requires looking at the image finely (at high resolution), which increases computation, while seeing large objects requires looking at a wide area at once. The mechanism for meeting both needs is "multi-scale" processing, which uses feature maps at several resolutions together, covered in Chapter 8.
3. The same object gets predicted multiple times
With plenty of candidates, several candidates near one object can each easily answer "there is a circle here". The boxes differ slightly, but the predictions actually point to the same circle. Left alone, one circle gets counted as three. How to remove these duplicate predictions is one of the oldest concerns in detector design.
4. Most of the image is background
Most candidates are not responsible for any object. Suppose a Shape World image is divided into a 6×6 grid of 36 cells with one candidate per cell. If there are two objects, at most 2 cells contain an object center, and for the remaining 34 cells the correct answer is "nothing". That is \(34 / 36 \approx 94\%\).
A situation like this, where one answer (here "nothing", that is, background) vastly outnumbers the others, is called class imbalance. When the imbalance is severe, a detector can be right most of the time just by answering "nothing everywhere", and it never learns to actually find objects. In real detectors the imbalance is much worse. The RetinaNet paper (Lin et al., 2017) notes that a detector scanning the whole image densely evaluates about 100,000 candidate locations per image, and that during training the ratio of objects to background can reach 1 : 1000. The focal loss proposed in that paper is calculated by hand in Chapter 4.
Figure 1-3 of the original tutorial shows two of these difficulties side by side. On the left, the fifth image of Figure 1-1 is divided into a 6×6 grid. Of the 36 cells, only the two shaded cells contain an object center (dot), and for the other 34 cells (94%) the correct answer is "nothing". On the right, three similar predictions overlap on a single circle (circle 0.92 as a solid line, circle 0.85 and circle 0.61 as dashed lines; the scores are made up for illustration). The boxes differ slightly but point to the same object, so there is only one circle and only one prediction should remain. Without removing the duplicates, the circle would be counted three times.
5. It has to be fast
Detectors often work attached to a camera feed. To keep up with a camera shooting 30 frames per second, each image must be processed in about 33 milliseconds (\(1000 \div 30 \approx 33.3\)). Moreover, detectors usually run not on large servers but on a small computer in a car or an industrial PC on a factory line. A detector that is accurate but slow is unusable, and so is one that is fast but inaccurate. This tradeoff is examined in detail in the "real-time" section later.
| Difficulty | In one line | Typical solution | Details |
| Unknown count | The number of answers varies by image and has no order | A fixed number of candidates + "nothing", matching predictions to ground truth | Ch. 7 |
| Varied size and position | Small and large, anywhere | Looking at features at several resolutions together | Ch. 8 |
| Duplicate predictions | Several predictions for one object | Removing them in post-processing (NMS), or training to output only one from the start | Ch. 3, 7 |
| Class imbalance | Most candidates are background | Down-weighting the loss of easy background (focal loss, etc.) | Ch. 4, 11 |
| Speed | Must answer within a fixed time | Lightweight architectures, searching the accuracy–latency tradeoff | Ch. 9, 12 |
The lineage of detectors
Since around 2013, deep learning detectors have developed along three main branches: two-stage detectors, one-stage detectors, and the DETR family. RF-DETR sits on the newest twig of the third branch. Each branch differs in "what serves as a candidate" and "how duplicates are removed", so keep an eye on those two questions as you follow along. Years below are the year each paper first appeared on arXiv.
Two-stage detectors: propose candidates, then classify
The first idea to succeed was to split the problem in two. Image classification was already working well, so if something picked out "regions likely to contain an object", you could crop those regions and feed them to a classifier. A rectangle picked out as likely to contain an object is called a region proposal, and a detector that works in two stages, (1) generating region proposals and (2) classifying each proposal, is called a two-stage detector.
- R-CNN (Girshick, Donahue, Darrell, Malik, 2013). The name is short for "Regions with CNN features". It extracts about 2,000 region proposals from an image, computes features for each proposal with a convolutional neural network (CNN), and decides what each one is with per-class classifiers. Overlapping predictions are removed with NMS, explained later. The paper reported raising mean average precision (mAP) on PASCAL VOC, the standard benchmark at the time, by more than 30% (relative) over the previous best, showing that deep learning works for detection too. However, feeding 2,000 proposals through the network one by one was slow. The follow-up Fast R-CNN paper noted that with a large network (VGG16), R-CNN takes 47 seconds per image even on a GPU.
- Fast R-CNN (Girshick, 2015). Instead of running the network on each proposal, it runs the network once on the whole image to produce a feature map, then crops only the parts of the feature map that correspond to each region proposal and classifies them. This eliminated the waste of repeating the same computation 2,000 times. The paper reported test time 213 times faster than R-CNN with VGG16. But that figure excluded the time to generate region proposals. Proposals were still produced by a separate algorithm outside the network, and that had now become the slowest part.
- Faster R-CNN (Ren, He, Girshick, Sun, 2015). It handed region proposal generation to the network as well, by attaching a small network (RPN, Region Proposal Network) that takes the same feature map used for classification and outputs region proposals. The paper described getting region proposals "nearly cost-free" this way, and reported processing 5 images per second for all stages combined with VGG16. This paper introduced the mechanism called anchors (explained below).
- Mask R-CNN (He, Gkioxari, Dollár, Girshick, 2017). A model that adds one more branch to Faster R-CNN for predicting masks, so that it also performs instance segmentation.
Two-stage detectors were accurate, but because each proposal had to go through a second stage, their structure was complex and hard to make fast.
One-stage detectors: all at once from a grid
"Instead of generating candidates separately, why not scan the image once and output boxes and classes directly?" A detector that drops the region proposal stage in this way is called a one-stage detector (also single-stage detector).
- YOLO (Redmon, Divvala, Girshick, Farhadi, 2015). Short for "You Only Look Once". It divides the image into an S×S grid (7×7 in the paper) and sets the rule that the cell containing an object's center is responsible for that object. Each cell outputs a few boxes and class probabilities all at once, so the network only has to run once. The left image of Figure 1-3 shows exactly this idea. The paper reported that the base model processes 45 images per second, while also acknowledging that its box localization was less accurate than the best detectors of the time.
- SSD (Liu et al., 2015). "Single Shot MultiBox Detector". At every position on the feature map it lays out several "default boxes" of different sizes and aspect ratios, and for each default box predicts class scores and "how much the default box must be adjusted to fit the object". It predicts from several feature maps at different resolutions, splitting large and small objects among them.
- RetinaNet (Lin, Goyal, Girshick, He, Dollár, 2017). It diagnosed class imbalance, described above, as the main reason one-stage detectors were less accurate than two-stage ones, and proposed the focal loss, which down-weights the loss of easy background candidates. This idea carries over into RF-DETR's loss as well (Chapter 11).
- Later YOLOs. YOLO became a long series as various researchers revised its architecture, data augmentation, and training techniques. The ones the RF-DETR paper compares against are YOLOv8 (2023) and YOLO11 (2024). Fast and easy to use, YOLO was for a long time synonymous with real-time detection.
Hand-designed components: anchors and NMS
Whether two-stage or one-stage, the detectors above contain components whose rules are set and inserted by people rather than learned by the network. The DETR paper called these hand-designed components. There are two main ones.
First, anchors (anchor boxes). These are reference boxes laid out over the image in advance. Faster R-CNN introduced them (SSD's "default boxes" are the same idea), placing several boxes of different sizes and aspect ratios at every position on the feature map. Instead of predicting boxes from scratch, the detector only answers, for each anchor, "is there an object near this anchor?" and "if so, how much should the anchor be shifted and stretched?" Making "small corrections" is easier than getting all four numbers right outright, so training goes well. In the terms of the earlier section, the anchors are the candidates. Anchors are a nuisance for the following reasons.
- People must choose the anchors' sizes, aspect ratios, and number. When the data changes (for example, data with many tall, thin utility poles), they must be chosen again.
- The rules that decide "which anchor is responsible for which ground-truth object" (assign it if the overlap exceeds some amount, etc.) are also set by people.
- There are thousands to tens of thousands of anchors and most are background, so anchors themselves bring about class imbalance.
Second, NMS (non-maximum suppression). This is post-processing that removes duplicate predictions. It is a rule run separately after the network has produced all its answers, and its outline is as follows.
- Sort predictions by score, highest first.
- "Keep" the prediction with the highest score.
- Discard all remaining predictions that overlap heavily with the kept one. The threshold that defines "heavily" is set by people.
- Repeat steps 2–3 on the remaining predictions.
For the right image of Figure 1-3, the solid box with score 0.92 is kept, and the two dashed boxes that overlap it heavily are discarded. The measure of "how much two boxes overlap" (IoU) is covered in Chapter 2, and the implementation of NMS in Chapter 3. NMS is a nuisance for these reasons.
- People must pick the threshold. Too strict and duplicates remain; too loose and it removes distinct objects that are close together (two people standing side by side). The right value differs by dataset.
- It is separate from training. The network is trained without knowing that NMS comes after it. The path "from input to final answer" cannot be trained as one piece.
- It takes time. The more predictions, the longer NMS takes, and that time varies by image. The RT-DETR paper pointed out that NMS reduces both YOLO's speed and its accuracy.
Hand-designed components are not simply bad. Anchors and NMS are effective mechanisms that supported detectors for nearly a decade, and many detectors still use them. The problem is that they embed "numbers chosen by people", so they need retuning every time you move to new data, and they prevent the whole system from being trained at once. This concern ties directly to the RF-DETR paper's stated goal of "a detector that transfers well to many datasets".
DETR: detection as set prediction
In 2020, Carion and other researchers at Facebook AI introduced DETR (DEtection TRansformer). The starting point was the fact noted at the beginning of this chapter: a detector's answer is a set, so train it to output the set directly.
- Keep a fixed number of "answer slots". DETR holds 100 learned vectors and, after looking at the image, outputs one prediction (box + class, or "no object") per vector. These vectors are called object queries. In the earlier analogy, they are the 100 slots on the answer sheet. Unlike anchors, they are not tied to fixed positions on the image.
- Match predictions to ground truth one-to-one. During training, it takes the 100 predictions and the handful of ground-truth objects and finds the one-to-one matching with the lowest total cost (Hungarian matching). Each ground-truth object is assigned to exactly one prediction, and predictions left unmatched get "no object" as their target.
- So duplicates disappear on their own. If two slots predict the same circle, one of them goes unmatched and is penalized. As training progresses, the slots divide up different objects among themselves. No NMS is needed.
The abstract of the DETR paper summarizes this as removing the need for "hand-designed components like a non-maximum suppression procedure or anchor generation". A detector trained as one piece from input to final answer, with no human-inserted post-processing, is called an end-to-end detector. Its architecture is a CNN backbone followed by a Transformer encoder and decoder. You will build attention and the Transformer yourself in Chapter 5, and DETR in Chapter 7.
Figure 1-4 of the original tutorial compares the processing order of the three branches in three rows.
- Two-stage (R-CNN family): image → (1) generate region proposals (hundreds to thousands) → (2) classify each proposal (class + box refinement) → NMS → result.
- One-stage (YOLO, SSD): image → one network pass (class + box all at once for each grid cell or anchor) → NMS → result.
- DETR family (including RF-DETR): image → one network pass (N queries → N predictions, mostly "no object"; trained not to produce duplicates) → result.
NMS is post-processing driven by human-set rules and is drawn as a dashed box in the figure. The biggest difference is that the DETR family has no dashed box.
What to read from this figure is the direction in which the number of boxes shrinks. Two-stage detectors have two network components and one post-processing step, one-stage detectors have one network and one post-processing step, and the DETR family has only one network. Fewer stages mean a simpler structure, the whole system can be trained with a single loss, and processing time depends less on image content (how many predictions came out).
The original DETR, however, had clear weaknesses. Combining what the paper itself acknowledged with what the follow-up Deformable DETR paper pointed out:
- Training is very slow. It needed 500 epochs (500 passes over the whole dataset) on COCO. The Deformable DETR paper noted that this is 10–20 times as long as Faster R-CNN.
- It is weak on small objects. The DETR paper reported that it beats Faster R-CNN on large objects but falls behind on small ones.
- Computation is heavy. In attention, every position in the feature map attends to every other position, so raising the feature map's resolution to see small objects makes computation grow rapidly (calculated in Chapter 5).
Deformable DETR and the real-time DETRs
Later research moved toward removing these weaknesses one by one while keeping DETR's strengths (end-to-end, no NMS).
- Deformable DETR (Zhu et al., 2020). Instead of looking at every position, it proposed deformable attention, which looks at only a few selected spots around a reference point. Where to look is also learned. The paper reported better performance than DETR (especially on small objects) with one-tenth the epochs. RF-DETR's decoder still uses this operation. → Chapter 8
- RT-DETR (Zhao et al., 2023). The paper's title is "DETRs Beat YOLOs on Real-time Object Detection". It introduced an encoder that processes multi-resolution features cheaply and a method for choosing good initial queries for the decoder, and claimed to have built, to the authors' knowledge, the first "real-time end-to-end detector". It also showed that speed can be adjusted without retraining by changing the number of decoder layers, an idea RF-DETR uses much more broadly. → Chapter 9
- LW-DETR (Chen et al., 2024). "Light-Weight DETR". Its structure is very simple: ViT encoder + projector + shallow DETR decoder. Instead of a CNN backbone, it uses ViT (Chapter 6), which cuts the image into patches and feeds them to a Transformer, and to reduce computation it alternates window attention, where only nearby patches attend to each other, with global attention, where all patches attend to each other. RF-DETR is a modified version of exactly this LW-DETR. → Chapter 9
- D-FINE (Peng et al., 2024). A real-time DETR that improves box localization by representing each of the box's four edges as a probability distribution and refining it step by step, instead of predicting a single number per edge. It is the model the RF-DETR paper compares against most often.
- RF-DETR (Robinson, Robicheaux, Popov, Ramanan, Peri, 2025). Released by researchers at Roboflow and Carnegie Mellon University and presented at ICLR 2026. The paper's title is "RF-DETR: Neural Architecture Search for Real-Time Detection Transformers". It is the protagonist of the rest of this chapter and of the whole tutorial.
Timeline at a glance
Figure 1-5 of the original tutorial is a timeline that lays detectors out by year in four rows (branches). The two-stage row has R-CNN (2013), Fast R-CNN and Faster R-CNN (2015), and Mask R-CNN (2017). The one-stage row has YOLO and SSD (2015), RetinaNet (2017), YOLOv8 (2023), and YOLO11 (2024). The DETR-family row has DETR and Deformable DETR (2020), RT-DETR (2023), LW-DETR and D-FINE (2024), and RF-DETR (2025) with a bold border. The bottom row, "Ingredients", holds DINOv2 and GroundingDINO (2023) and RF100-VL (2025), which RF-DETR uses as ingredients or as points of comparison. Years are the year of first arXiv posting, and horizontal spacing is not proportional to actual years.
There are three trends to read from the timeline. First, from 2013 to 2017, two-stage and one-stage detectors developed side by side. Second, DETR opened the third row in 2020, but it only became fast enough for real-time detection with RT-DETR in 2023. Third, RF-DETR sits where the third row (LW-DETR) meets the bottom row (the pretrained model DINOv2 and the benchmark RF100-VL).
| Year | Model (authors) | Branch | Key idea | Tutorial |
| 2013 | R-CNN (Girshick et al.) | Two-stage | Extracts about 2,000 region proposals and classifies each with a CNN | Ch. 1 |
| 2015 | Fast R-CNN (Girshick) | Two-stage | Runs the CNN once on the whole image and crops only the proposal regions for classification | Ch. 1 |
| 2015 | Faster R-CNN (Ren et al.) | Two-stage | Region proposals are also generated by a network (RPN). Introduces anchors | Ch. 1 |
| 2015 | YOLO (Redmon et al.) | One-stage | Predicts boxes and classes for each grid cell in one pass | Ch. 1 |
| 2015 | SSD (Liu et al.) | One-stage | Predicts for each default box on feature maps at several resolutions | Ch. 1 |
| 2017 | RetinaNet (Lin et al.) | One-stage | Tames class imbalance with the focal loss | Ch. 4 |
| 2017 | Mask R-CNN (He et al.) | Two-stage | Adds a mask branch to Faster R-CNN for instance segmentation | Ch. 13 |
| 2020 | DETR (Carion et al.) | DETR | Set prediction + one-to-one matching. No anchors or NMS | Ch. 7 |
| 2020 | Deformable DETR (Zhu et al.) | DETR | Deformable attention that looks at only a few selected spots. Training becomes 10 times faster | Ch. 8 |
| 2023 | RT-DETR (Zhao et al.) | DETR | Claims to be the first end-to-end detector that runs in real time | Ch. 9 |
| 2023 | DINOv2 (Oquab et al.) | Ingredient | A ViT pretrained on 142 million images without labels | Ch. 6 |
| 2023 | GroundingDINO (Liu et al.) | Ingredient | An open-vocabulary detector that finds objects from written names or sentences | Ch. 1 |
| 2024 | LW-DETR (Chen et al.) | DETR | ViT encoder + projector + shallow decoder | Ch. 9 |
| 2024 | D-FINE (Peng et al.) | DETR | Refines box edges represented as probability distributions | Ch. 1 |
| 2025 | RF100-VL (Robicheaux et al.) | Ingredient | A benchmark of 100 datasets from different domains | Ch. 1 |
| 2025 | RF-DETR (Robinson et al.) | DETR | DINOv2 backbone + weight-sharing NAS + standardized latency measurement | Ch. 10–13 |
What does "real-time" mean?
The RF-DETR paper's title includes "Real-Time". For a detector, real-time means "it produces an answer within the time the application requires". For a 30-frames-per-second camera the limit is 33 milliseconds per image; at 60 frames per second it is 17 milliseconds. There is no single fixed number, and each paper states its own criterion. The RF-DETR paper treats detectors with latency of 40 milliseconds or less on the standard hardware described later (an NVIDIA T4 GPU) as real-time detectors in its comparisons.
Latency and throughput
There are two yardsticks for speed.
- Latency: The time from feeding in one image to getting the answer. The unit is milliseconds (ms, one-thousandth of a second), and smaller is better. It matters where each individual answer must arrive quickly, as in self-driving, where the system decides "should I brake?"
- Throughput: The number of images processed in a given time. The unit is frames per second (FPS), and larger is better. It matters where finishing the whole job quickly is what counts, as in analyzing tens of thousands of hours of stored video in bulk.
If images are processed one at a time in sequence, the two are reciprocals. If latency is \(t\) milliseconds, the number of images processed in one second (1,000 milliseconds) is as follows.
\(\text{초당 처리 장 수} = \frac{1000}{t}\)
(The left-hand side is images processed per second.) Using values from Table 2 of the RF-DETR paper, images per second computed from latency are as follows.
\(\begin{align} t = 2.3 \;&\Rightarrow\; \frac{1000}{2.3} \approx 435 \\ t = 4.4 \;&\Rightarrow\; \frac{1000}{4.4} \approx 227 \\ t = 17.2 \;&\Rightarrow\; \frac{1000}{17.2} \approx 58 \end{align}\)
- RF-DETR (N) has a latency of 2.3 milliseconds. Dividing 1,000 milliseconds by the time per image gives the number of images per second: about 435.
- RF-DETR (M) takes 4.4 milliseconds. By the same method, about 227 images. Latency roughly doubles, so images per second roughly halves.
- The largest real-time model, RF-DETR (2XL), takes 17.2 milliseconds, about 58 images per second. It uses about half the budget of a 30-frames-per-second camera (33.3 milliseconds).
This division is a rough estimate. \(1000 / t\) assumes running "only the detector, one image at a time, without pause". A real system adds time for reading images from the camera and resizing them, and for passing results on. Conversely, feeding several images together (a batch) can increase throughput. The RF-DETR paper also states that its measurement method is meant not to capture sustained throughput but to make latency give the same value when measured repeatedly (caption of Table 1). So the numbers above should be read only as "roughly this fast".
The accuracy–latency tradeoff and the Pareto curve
The bigger a detector is made (more layers, higher input resolution), the more accurate it generally becomes, and the slower. Accuracy and latency are in a tradeoff: gaining one means giving up the other. So there is no single "best detector". A drone where every millisecond counts and medical image reading where accuracy is everything want different detectors.
It is like choosing a laptop. Some are light and slow, others heavy and fast, and you cannot simply say one is "better". But there is certainly no reason to buy a laptop that is both heavier and slower. Filter all of those out, and the list of "ones worth buying" that remains is the Pareto curve.
Plot several detectors as points on a chart with latency on the horizontal axis and accuracy on the vertical axis. Further left is faster and further up is more accurate, so up and to the left is the ideal direction. Figure 1-6 of the original tutorial is a conceptual accuracy–latency chart of this kind (not actual measurements), where each point is one model. The line joining six dark points, rising from lower left to upper right and gradually flattening, is the Pareto frontier, and faint points are scattered below and to the right of it. Up and to the left of faint point A is dark point B.
- Look at point A: point B lies up and to its left. B is both faster and more accurate than A. In this case we say "B dominates A". There is no reason to choose A.
- The dark points do not dominate each other. A point to the right is more accurate but slower, and a point to the left is faster but less accurate. Which to choose depends on the application's time budget.
- The line joining these points not dominated by any other point is called the Pareto frontier or Pareto curve (named after the Italian economist Vilfredo Pareto). When a detector paper says "our model is better", what it usually means precisely is "our models' Pareto curve lies up and to the left of others' curves".
- The curve flattens toward the right. This means that spending twice the latency raises accuracy only slightly. This is confirmed with real numbers in a later table.
Normally each point on a Pareto curve is a model designed and trained separately. YOLO's N, S, M, L, and X work this way. RF-DETR's most striking claim is that every point on its Pareto curve on COCO came from a single training run (caption of Figure 1 in the paper). How that is possible is the subject of Chapter 12, where you will also draw a Pareto curve yourself from experiments in Shape World.
Latency is hard to measure fairly
Can the horizontal axis of the Pareto curve be trusted? The RF-DETR paper argues that it cannot: the latency of the same model has been reported differently from paper to paper. For example, the latency of LW-DETR as re-measured by the D-FINE paper was reportedly 25% faster than the value the LW-DETR paper itself reported. The causes and remedies the paper identifies are as follows.
- GPU power throttling. Running nonstop makes the GPU heat up and slow itself down, which makes measurements fluctuate. The paper's remedy is to pause 200 milliseconds between forward passes.
- Leaving out NMS time. The YOLO family often reports latency excluding NMS time, which the paper points out is unfair when comparing against end-to-end detectors that have no NMS.
- Measuring accuracy and latency on different models. There is a practice of measuring latency on a fast model with numbers reduced to 16 bits (FP16) while measuring accuracy on a 32-bit model (FP32), but reducing to 16 bits can lower accuracy. The paper argues that both should be measured on the same model file.
This critique and the standardized measurement procedure are the RF-DETR paper's third contribution. Details, and an experiment where you measure latency yourself, are in Chapters 12 and 14. For now, just remember that "all latencies in this chapter's tables were re-measured by the RF-DETR paper on the same hardware with the same method".
The problem RF-DETR sets out to solve
The content of this section consists of the paper's claims. They are presented along with the experiments cited as evidence, but phrased as "the paper claims that …" so they are not read as facts independently verified by the tutorial.
Open-vocabulary detectors and specialist detectors
The paper divides today's detectors into two groups.
- Specialist detectors (closed-vocabulary detectors): Detectors that answer only within the class list fixed at training time. R-CNN, YOLO, DETR, LW-DETR, and D-FINE, all covered so far, belong here. A detector trained on Shape World knows only circles, rectangles, and triangles; show it a star and it cannot answer "star". They are also called closed-vocabulary detectors because the vocabulary (class list) is closed. They are light and fast.
- Open-vocabulary detectors: Detectors that take the target to find as text. Feed in a word or sentence such as "red umbrella" or "the lion on the left" together with the image, and they output the matching boxes. The vocabulary is open because you can give names not seen during training. Representative examples are GroundingDINO (Liu et al., 2023) and YOLO-World. This ability comes from vision-language models (VLMs) trained on enormous numbers of image–text pairs collected from the internet. They must also carry a component that understands text (a text encoder), so they are heavy and slow.
| Comparison | Specialist (closed-vocabulary) detector | Open-vocabulary detector |
| What it finds | The class list fixed at training time | Anything described in text |
| When a new class is needed | Retrain on labeled data (fine-tuning) | Just change the name you give it (when it works) |
| Size and speed | Small and fast | Large and slow |
| Examples | YOLO, RT-DETR, LW-DETR, D-FINE, RF-DETR | GroundingDINO, YOLO-World |
| Weakness according to the paper | Overfit to COCO | Does not work well on kinds of data not seen during pretraining |
The paper's diagnosis is this. Open-vocabulary detectors find common targets such as cars, trucks, and pedestrians well without separate training, but performance drops sharply on targets that were rare in the pretraining data (lesions in medical images, specific parts in a factory, aerial photos). Fine-tuning on such data raises accuracy, but they remain slow. Specialist detectors, on the other hand, are fast but have not been as accurate as fine-tuned open-vocabulary detectors. The paper's goal is therefore to combine the strengths of both. In the paper's words, it "modernizes specialist detectors by combining internet-scale pretraining with real-time architectures".
- Key point
- RF-DETR is a specialist detector. It takes no text input and finds only a fixed set of classes. But it brings in the root of the open-vocabulary detectors' strength, namely knowledge learned in advance from internet-scale images, through its backbone (DINOv2). It does not bring in a text encoder, so it stays light.
The claim that detectors are overfit to COCO
For researchers to compare detectors, they need the same exam. A test set up so that everyone scores on the same data in the same way is called a benchmark. The most widely used benchmark in object detection is COCO (Common Objects in Context; Lin et al., 2014). As the name says, it is a collection of photos of common objects in everyday scenes; according to its paper, about 328,000 photos with 2.5 million labeled objects. The detection benchmark uses 80 classes such as person, bicycle, car, dog, and chair, and papers usually report scores measured on COCO's validation set.
For more than a decade, every detector has competed on COCO scores. The RF-DETR paper claims this has a side effect: recent specialist detectors have tuned the following three things closely to COCO to squeeze out a little more COCO score.
- Model architecture. Architectures fitted to COCO's distribution of image and object sizes.
- Learning rate schedules. For example, decaying the learning rate along a cosine curve requires knowing in advance "how many steps the whole training run has". The paper points out that this can be tuned well for a single fixed-size dataset like COCO, but does not suit datasets of widely varying size.
- Data augmentation schedules. Even when to turn strong augmentations (flipping, cropping, and mixing images) on and off is tuned to COCO. The paper gives vertical flipping as an example: if a self-driving car's pedestrian detector is trained on vertically flipped images, it may mistakenly detect a person's reflection in a puddle as a person.
The paper's claim is that a detector tuned too tightly to one exam does not perform as well as expected on real data whose character differs from that exam (in objects per image, number of classes, or dataset size). It cites one observation as evidence. D-FINE is built on RT-DETR and scores higher than RT-DETR on COCO. Yet when measured on RF100-VL (described below), RT-DETR beat D-FINE on one metric (AP50) (paper Table 4: RT-DETR (M) 85.7, D-FINE (M) 85.5). The paper interprets this as a sign that D-FINE's training settings may be overfit to COCO.
RF-DETR therefore keeps its training method deliberately simple. The paper calls this a "scheduler-free" approach: no learning rate warmup, and only horizontal flips and random crops for augmentation. Detailed settings are covered in Chapter 11.
Claims and facts should be read separately. "Overfit to COCO" is the RF-DETR authors' interpretation. It is also worth knowing that several of the authors created RF100-VL, and that Roboflow is the company that runs that data. That does not mean the claim is wrong. The lesson "don't choose a detector by its score on a single benchmark" is worth taking to heart no matter who says it. But as the later tables show, RF-DETR does not beat every competitor at every size on COCO score alone, and the paper does not hide this.
RF100-VL: one hundred different datasets
To measure "does it do well on many kinds of real data", the RF-DETR paper uses a second benchmark alongside COCO: RF100-VL (Roboflow100-VL; Robicheaux et al., 2025).
- It is a collection of 100 different object detection datasets selected from Roboflow Universe (where users upload datasets).
- According to the RF100-VL paper, the datasets were chosen to contain concepts rarely seen in internet-scale pretraining: other imaging modalities such as X-ray, thermal, and aerial imagery; class names that are technical terms or abbreviations; distinctions such as material type. The 100 datasets are grouped into seven categories.
- That paper reported that models like GroundingDINO, without additional training, reach less than 2% accuracy on the hard medical imaging datasets among them. This is evidence that open-vocabulary detectors cannot find "anything".
- The score is the average of training and evaluating a detector on each of the 100 datasets. The RF-DETR paper considers that, because the datasets are this diverse, the average score serves as a proxy for "does it transfer well to any new domain".
One more dataset appears. Objects365 is a large-scale object detection dataset created by Shao et al. (2019), and in RF-DETR it serves not as an exam but as a textbook: before training on COCO or RF100-VL, the whole detector is first trained once on Objects365 (pretraining). The LW-DETR paper reported that this pretraining helps the DETR family greatly, and RF-DETR follows suit. The two-step sequence of pretraining and fine-tuning is covered in detail in Chapter 6.
| Dataset | What it is | Role in the RF-DETR paper |
| COCO | Everyday photos, 80 classes. The flagship detection benchmark | The exam for fair comparison with prior work |
| RF100-VL | A collection of 100 datasets from different domains | The exam for how well it transfers to real data |
| Objects365 | A large-scale object detection dataset | The textbook for training the detector in advance (pretraining) |
| Shape World | 96×96 toy data made for this tutorial | (Unrelated to the paper) The stage for all of this tutorial's exercises |
RF-DETR at a glance
In one sentence, RF-DETR is a real-time detector that takes the LW-DETR skeleton, plugs in a DINOv2 backbone pretrained at internet scale, and adds a method (weight-sharing NAS) for obtaining thousands of models of different speeds from a single training run. First the architecture, then the three contributions the paper claims.
Architecture: from image to boxes
Figure 1-7 of the original tutorial is a conceptual diagram of RF-DETR's architecture (redrawn by the tutorial based on Figure 2 of the paper). The top row is the part that "understands the image": (1) image (e.g., 384×384 RGB) → (2) cut into patches (16×16 pieces → tokens, + position embeddings) → (3) DINOv2 ViT backbone (light cells = window attention blocks, dark cells = global attention blocks) → (4) projector (gathers tokens from several layers into a feature map for detection), and the result is a feature map (shape: channels × height × width). The bottom row is the part that "picks out objects": (5) query selection (scores how likely each feature-map position is to hold an object and picks the top 300 as the starting boxes of 300 queries) → (6) decoder layers × 2–6 (self-attention → deformable cross-attention → FFN, i.e., queries confer with each other → look into the feature map → tidy up; the decoder looks only at the parts of the feature map it needs) → (7) classification head (class, score) and box head (box), and (8) segmentation head (mask, RF-DETR-Seg only). The output is one (box, class, score) per query, used as the final answer as-is with no NMS. The layout of cells inside the backbone follows the notation in Appendix A of the paper.
Each component gets only one sentence here, with details deferred to the relevant chapter. It is fine if many words are unfamiliar for now. Just get used to "these components are arranged in this order"; if you come back after reading Chapter 10, every cell will make sense.
- Image. An RGB image resized to a fixed resolution (384×384 for the smallest model, N).
- Cutting into patches. The image is cut like a checkerboard into small 16×16-pixel pieces (patches), and each piece is turned into a vector of numbers (a token). A position embedding that says "which piece this is" is added. → Chapter 6
- DINOv2 ViT backbone. Twelve Transformer layers in which tokens attend to each other (attention) and are gradually transformed into meaningful representations. Since this component does most of the work of understanding the image, it is called the backbone. Its weights are not learned from scratch but start from values DINOv2 learned in advance from 142 million unlabeled images. To reduce computation, it alternates window attention blocks, where only nearby tokens attend to each other, with global attention blocks, where all tokens attend to each other. → Chapter 5 (attention), Chapter 6 (ViT and DINOv2), Chapter 9 (window attention), Chapter 10
- Projector. Takes tokens from several backbone layers, lays them back out in checkerboard form, concatenates them, and refines them with a few convolutional layers into a single feature map suited to detection. It is the bridge between backbone and decoder. → Chapters 9, 10
- Query selection. Scores every position of the feature map on "is an object likely here?", picks the 300 highest-scoring positions, and passes rough boxes at those positions to the decoder as starting points. It folds an idea similar to the two-stage detectors' "region proposals" into the network. → Chapters 8, 10
- Decoder. The 300 queries (300 answer slots) are refined as they pass through the layers. Each layer does three things in turn: with self-attention, queries attend to each other so they don't take on the same object; with deformable cross-attention, each looks at only a few spots around its own box in the feature map; and an FFN (a small neural network) organizes the information gathered. The number of layers is 2–6 depending on model size. → Chapters 5, 7, 8, 10
- Classification head and box head. Small output layers that read per-class scores and the four box numbers from each refined query. They are called heads because they sit at the end of the body and produce the answer. → Chapter 10
- Segmentation head (RF-DETR-Seg only). A lightweight component that outputs one additional mask per query. It is absent when only detecting. → Chapter 13
Two points about the architecture are worth stressing. First, there is no post-processing. The 300 predictions from the decoder are the final answer as-is (low-scoring ones are only filtered out with a threshold). Second, during training, heads are attached to the output of every decoder layer and a loss is applied to each. As a result, usable answers come out no matter which layer you stop at, and this is what makes the "number of decoder layers" knob, described below, possible.
Three contributions
The paper summarizes its contributions as three. In beginner-friendly terms:
Contribution 1. Well-trained eyes + a fast body. People who have seen many pictures pick up new objects quickly, too. DINOv2 is a model that learned "how to look at images" in advance by viewing 142 million images without labels (Chapter 6). RF-DETR plugs these eyes into the body of a real-time detector (LW-DETR). The paper reports that this raises accuracy substantially on small datasets, because the less data there is, the larger the share of prior knowledge. There is a cost: the DINOv2 backbone has more layers (12) than the backbone LW-DETR used (10), so it is slower. The paper says this loss is recovered by Contribution 2.
Contribution 2. A detector with five knobs. Normally, if you need a faster model, you design a smaller one and train it again from scratch. RF-DETR trains a single model while turning the five knobs below at random at every step. As a result, after training, the model is usable without retraining whatever position you set the knobs to. This is called weight-sharing NAS (neural architecture search).
| Knob | What it sets | Accuracy ↔ speed |
| ① Image resolution | How large to view the image | Higher sees small objects better but is slower |
| ② Patch size | How finely to cut the image | Smaller patches mean more tokens: more accurate but slower |
| ③ Number of windows | How many regions to split the image into in window attention blocks | More regions mean less computation but less mixing of distant information |
| ④ Number of decoder layers | How many times to refine the queries | Removing layers is faster and slightly less accurate |
| ⑤ Number of queries | How many answer slots to keep | Fewer is faster but lowers the cap on how many objects can be found |
After training, thousands of knob combinations are generated, their accuracy and latency are measured on validation data, and only the combinations on the Pareto frontier are kept. The paper states that it evaluated 6,468 combinations on COCO. This is exactly what "every point on the Pareto curve came from a single training run" means. For users, it means "you can choose the size that fits your data and your hardware without retraining". → Chapter 12
Contribution 3. Fixing the yardstick for speed. This is the latency measurement problem from the earlier section. The paper proposes a procedure that pauses 200 milliseconds between forward passes and measures accuracy and latency on the same model file, re-measures all the other detectors with that procedure to build its tables, and releases its measurement tool. → Chapter 12
- Key point: RF-DETR in three lines
- What it is: An NMS-free, real-time specialist detector built by modifying LW-DETR (plus an instance segmentation model, RF-DETR-Seg).
- What it changed: The backbone to DINOv2, training to weight-sharing NAS that "turns the knobs at random", and training settings to a simple, scheduler-free setup.
- Why: To pick the right accuracy–latency point on any data and any hardware, not just on COCO, without redesigning.
RF-DETR in numbers
The accuracy metric in the tables, AP (average precision), is a score that sums up in one number "how accurately and completely boxes were found, without false hits". Chapter 3 is devoted entirely to how it is computed. For now, it is enough to know that it is a score from 0 to 100, and higher is better. For a sense of scale, a 1–2 point AP difference on COCO is an improvement a paper can claim, and 5 points is a big difference.
All latencies were measured by the RF-DETR paper on an NVIDIA T4 GPU, using 16-bit (FP16) models converted with TensorRT (NVIDIA's inference optimization tool), following the standard procedure described above. The paper states that measurement jitter is at most 0.1 milliseconds, so values are given to one decimal place. In parameter counts, M means millions.
Configurations and performance by size
The following table combines Table 7 (configurations) and Tables 2 and 12 (performance) of the paper. Each row shows both "where the knobs were set" and "what the result was". All are COCO detection, and the number of queries is 300 for every size.
| Size | Resolution | Patch | Tokens per side | Windows | Decoder layers | Backbone | Parameters | Latency (ms) | AP |
| N (nano) | 384 | 16 | 24 | 2 | 2 | DINOv2-S | 30.5M | 2.3 | 48.0 |
| S (small) | 512 | 16 | 32 | 2 | 3 | DINOv2-S | 32.1M | 3.5 | 52.9 |
| M (medium) | 576 | 16 | 36 | 2 | 4 | DINOv2-S | 33.7M | 4.4 | 54.7 |
| L (large) | 704 | 16 | 44 | 2 | 4 | DINOv2-S | 33.9M | 6.8 | 56.5 |
| XL | 700 | 20 | 35 | 1 | 5 | DINOv2-B | 126.4M | 11.5 | 58.6 |
| 2XL | 880 | 20 | 44 | 2 | 5 | DINOv2-B | 126.9M | 17.2 | 60.1 |
| Max | 828 | 12 | 69 | 1 | 6 | DINOv2-B | 132.4M | 98.0 | 61.8 |
The "tokens per side" column is not in the paper's tables; the tutorial added it by dividing resolution by patch size. If \(R\) is the resolution and \(P\) the patch size, \(R / P\) patches fit along one side of the image, and the total number of patches (tokens) in the image is its square.
\(\begin{align} \frac{R}{P} &= \frac{384}{16} = 24 \\ \left(\frac{R}{P}\right)^2 &= 24^2 = 576 \\ \frac{576}{16} &= 36, \qquad 36^2 = 1296 \\ \frac{1296}{576} &= 2.25 \end{align}\)
- Model N. Cutting an image 384 pixels on a side into patches 16 pixels on a side fits 24 patches across and 24 down.
- 24 across × 24 down makes 576 patches in total. The backbone handles these 576 tokens.
- Do the same calculation for model M (resolution 576, patch 16): 36 per side, 1,296 in total.
- Resolution grew only 1.5 times (\(576 / 384\)), but the token count grows \(1.5^2 = 2.25\) times. This is why raising resolution makes computation grow quickly.
What to read from the table:
- N through L are almost the same model. The backbone is the same (DINOv2-S), and the parameter count barely changes, from 30.5M to 33.9M. Only the resolution and number of decoder layers differ, that is, only the knob positions. Yet latency triples from 2.3 to 6.8 milliseconds, and AP changes by 8.5 points, from 48.0 to 56.5. This is exactly what the paper means by "latency can differ greatly even with similar parameter counts". Model size (parameter count) and speed are different things.
- From XL onward the backbone gets bigger (DINOv2-B). The parameter count nearly quadruples.
- Each point gets more expensive further down the table. N → S gains 4.9 points for 1.2 extra milliseconds, but 2XL → Max gains 1.7 points for 80.8 extra milliseconds. These are the real numbers behind the curve flattening toward the right in Figure 1-6.
- 2XL reaches 60.1 AP. The paper claims this is "the first real-time detector to exceed 60 AP on COCO" (to the authors' knowledge). Max, at 98.0 milliseconds, exceeds the 40-millisecond real-time threshold the paper uses.
- The knobs do not always move in one direction. L and 2XL have the same 44 tokens per side, and XL (35) actually has fewer than L (44). It is hard for people to guess which combinations are good, so this was left to the search. Appendix L of the paper reports that performance is more closely tied to the ratio of resolution to patch size (that is, the token count) than to either one alone.
The "Windows" column copies the "Windows" values from Table 7 of the paper. In the released code, this value (num_windows) means how many parts each side is divided into, so 2 splits the image into 2×2 = 4 regions. With 1 there is no split, so every block becomes equivalent to global attention. This is checked against the code in Chapter 10.
Comparison with other detectors
The following is excerpted from Table 2 of the paper. Models with similar latency are grouped together, and all values are AP on the COCO validation set.
| Group | Model | Branch | Parameters | Latency (ms) | AP |
| N | YOLO11 (N) | One-stage + NMS | 2.6M | 2.2 | 37.1 |
| LW-DETR (T) | DETR | 12.1M | 1.9 | 42.9 | |
| D-FINE (N) | DETR | 3.8M | 2.1 | 42.7 | |
| RF-DETR (N) | DETR | 30.5M | 2.3 | 48.0 | |
| S | YOLO11 (S) | One-stage + NMS | 9.4M | 3.2 | 44.1 |
| LW-DETR (S) | DETR | 14.6M | 2.6 | 48.0 | |
| D-FINE (S) | DETR | 10.2M | 3.5 | 50.6 | |
| RF-DETR (S) | DETR | 32.1M | 3.5 | 52.9 | |
| M | YOLO11 (M) | One-stage + NMS | 20.1M | 5.1 | 48.3 |
| RT-DETR (R18) | DETR | 36.0M | 4.4 | 49.0 | |
| LW-DETR (M) | DETR | 28.2M | 4.4 | 52.6 | |
| D-FINE (M) | DETR | 19.2M | 5.4 | 55.0 | |
| RF-DETR (M) | DETR | 33.7M | 4.4 | 54.7 | |
| Large models | GroundingDINO (T), fine-tuned on COCO | Open-vocabulary | 173.0M | 427.6 ※ | 58.2 |
| RF-DETR (2XL) | DETR | 126.9M | 17.2 | 60.1 |
※ GroundingDINO cannot run on TensorRT, so its latency was measured in PyTorch. The measurement conditions differ from the rest, so treat this latency as a reference only. The paper also states that the 58.2 AP was not measured by the RF-DETR authors but taken from the value reported by a public implementation (mmdetection).
What to read from this table:
- The gap is largest at the small end. In the N group, RF-DETR scores \(48.0 - 42.7 = 5.3\) points higher than D-FINE and 5.1 points higher than LW-DETR. This is the "+5.3 AP" in the paper's abstract. Its latency of 2.3 milliseconds is a bit longer than D-FINE (2.1) and LW-DETR (1.9), which the paper describes as "similar latency".
- RF-DETR (N) scores about the same as YOLO11 (M) in less than half the time. 48.0 vs. 48.3, and 2.3 milliseconds vs. 5.1 milliseconds.
- In the M group, D-FINE (M) is 0.3 points higher (55.0 vs. 54.7), but 1 millisecond slower (5.4 vs. 4.4). Neither dominates the other, the same relationship as two dark points in Figure 1-6. Though not shown in the table, the same holds at larger sizes: in Table 12 of the paper, D-FINE (L) 57.2 and (XL) 59.3 are higher than RF-DETR (L) 56.5 and (XL) 58.6. The paper itself notes that "D-FINE (x-large) outperforms RF-DETR (x-large)". RF-DETR does not win at every size on COCO.
- RF-DETR has many parameters. In the N group, D-FINE has 3.8M and RF-DETR 30.5M, eight times as many, yet their latency is similar. The point from the previous table, "size and speed are different", shows up again. Still, on devices with tight model file size or memory limits, parameter count also has to be considered.
- It surpasses a fine-tuned open-vocabulary detector. RF-DETR (2XL) is 1.9 points higher than GroundingDINO (T).
Results beyond COCO are in Table 4 of the paper, on RF100-VL (the average over 100 datasets). Only a few rows are shown here.
| Model | Latency (ms) | RF100-VL AP |
| YOLO11 (M) | 5.1 | 57.0 |
| LW-DETR (N) | 1.9 | 57.1 |
| D-FINE (N) | 2.0 | 58.2 |
| RF-DETR (N) | 2.5 | 57.8 (58.6 with fine-tuning after the search) |
| RF-DETR (M) | 4.6 | 61.7 (62.0) |
| GroundingDINO (T), fine-tuned | 309.9 ※ | 62.3 |
| RF-DETR (2XL) | 15.6 | 63.3 (63.5) |
※ Measured in PyTorch (for the same reason as in the table above).
RF-DETR (2XL) is \(63.5 - 62.3 = 1.2\) points higher than GroundingDINO (T), with about \(309.9 \div 15.6 \approx 20\) times lower latency. This is the "+1.2 AP while 20× faster" in the abstract (the 1.2 points use the fine-tuned value, with the caveat that latency was measured under different conditions). The table also plainly shows that at size N, D-FINE (N) at 58.2 is higher than RF-DETR (N) without fine-tuning at 57.8. And YOLO11 stays at 57.0 even at size M; the paper reports that the YOLO family's RF100-VL score does not improve as the model grows.
One line on instance segmentation (Table 3 of the paper): RF-DETR-Seg (N) reaches 40.3 mask AP at 3.4 milliseconds, ahead of every size of YOLO11 segmentation model the paper measured. Details are in Chapter 13.
Paper figures and README figures
RF-DETR is an open package (rfdetr) still under development, so the table in the repository README differs slightly from the paper's tables in places. The COCO AP in the README as checked by the tutorial (November 2026) is as follows.
| Size | AP in paper Tables 2 and 12 | AP in README |
| N | 48.0 | 48.4 |
| S | 52.9 | 53.0 |
| M | 54.7 | 54.7 |
| L | 56.5 | 56.5 |
The differences are small, 0.1–0.4 points. The released weights may have been updated after the paper was written, but the tutorial could not confirm the reason. So whenever the tutorial says "the paper's figures", it always means the paper's tables, and values obtained by running the package are recorded separately in Chapter 14 as "actually measured values". The two are not mixed. Also, according to the README, the N, S, M, and L detection models and all segmentation models are provided under the Apache 2.0 license, while larger detection models such as XL and 2XL are provided in a separate package (rfdetr[plus]) under a different license. This is worth checking for practical use.
From LW-DETR to RF-DETR: reading the ablation study
RF-DETR changed many things from LW-DETR at once, which raises the question "what helped, and by how much?" An experiment that answers this by adding or removing the changes one at a time and measuring performance is called an ablation study. Table 5 of the paper is one: it starts from LW-DETR (M) and changes one thing per row until it reaches RF-DETR (M). The most informative table in a deep learning paper is usually the ablation table, so it is worth learning how to read one.
| Step | Change | Parameters | Latency (ms) | AP | Difference from previous row |
| 0 | LW-DETR (M) - starting point | 28.2M | 4.4 | 52.6 | - |
| 1 | + gentler training settings | 28.2M | 4.4 | 51.6 | −1.0 |
| 2 | + DINOv2 backbone | 32.3M | 4.7 | 53.6 | +2.0 |
| 3 | + additional Objects365 pretraining | 32.3M | 4.7 | 54.3 | +0.7 |
| 4 | + training with weight-sharing NAS | 32.3M | 4.7 | 54.6 | +0.3 |
| 5 | Patch 14 → 16, resolution 560 → 640 | 32.3M | 4.7 | 54.4 | −0.2 |
| 6 | Resolution 640 → 576 | 32.2M | 4.0 | 53.6 | −0.8 |
| 7 | Windows 4 → 2 | 32.2M | 4.3 | 54.3 | +0.7 |
| 8 | Decoder 3 layers → 4 layers | 33.7M | 4.4 | 54.6 | +0.3 |
Figure 1-8 of the original tutorial draws this table as a staircase. Steps 0–8 (LW-DETR (M), gentler settings, DINOv2, O365 added, NAS training, patch 16 and 640, resolution 576, windows 2, decoder 4 layers) are laid out horizontally, with AP above each point (52.6, 51.6, 53.6, 54.3, 54.6, 54.4, 53.6, 54.3, 54.6) and latency below (4.4, 4.4, 4.7, 4.7, 4.7, 4.7, 4.0, 4.3, 4.4 ms). The five points on the left (steps 0–4) change the training method, and the four points to the right of the dashed line (steps 5–8) only turn the knobs of the already trained model (no retraining). The key point is that the starting and ending latencies are the same, 4.4 milliseconds. Read step by step:
- Step 1: one step down (−1.0). The training settings were made gentler than LW-DETR's: a lower learning rate (4e-4 → 1e-4), replacing batch normalization in the projector with layer normalization, and so on. Why do this if the score drops? The paper gives two reasons. Switching to layer normalization allows training on ordinary GPUs with small memory (by accumulating gradients over several steps before updating), and the lower learning rate does less damage to the prior knowledge of DINOv2, which is plugged in at the next step. It is a step down taken in order to climb the steps that follow.
- Step 2: the biggest step (+2.0). The backbone is replaced with DINOv2. It recovers the lost point and gains one more. In exchange, the backbone grows to 12 layers and latency goes from 4.4 to 4.7 milliseconds. Table 6 of the paper reports that, under the same conditions, it also tried other pretrained backbones (SigLIPv2, SAM2's Hiera), and DINOv2 was the best.
- Step 3: +0.7. Objects365 pretraining is run longer. The paper explains that this compensates for the slower optimization caused by the lower learning rate.
- Step 4: +0.3. The training method is switched to weight-sharing NAS. The model configuration (patch 14, resolution 560) stays the same, yet the score rises. More interestingly, patch size 14 was not even in the list of knob values used during training. The paper interprets this as training with randomly turned knobs itself making the model more robust, like data augmentation, and calls it "architecture augmentation".
- Step 5: why latency stays the same. From here on, the model is not retrained; only the knobs are turned. Changing the patch from 14 to 16 and the resolution from 560 to 640 keeps the tokens per side the same: \(560 / 14 = 40\) and \(640 / 16 = 40\). So latency stays at 4.7 milliseconds and the score changes by only 0.2 points. This is one example of "token count matters" from the previous section.
- Step 6: buying speed. Resolution is lowered to 576 to reduce tokens. Latency drops from 4.7 to 4.0 milliseconds and the score falls by 0.8 points.
- Steps 7 and 8: spending the spare time to buy back accuracy. Windows are reduced from 4 to 2 (+0.7 points, +0.3 milliseconds), and the decoder is increased to 4 layers (+0.3 points, +0.1 milliseconds). Fewer windows means each region is larger, so computation increases but information mixes across greater distances.
The end point is 54.6 AP at 4.4 milliseconds: the same latency as the starting point, LW-DETR (M), and 2.0 points higher. The 0.3 milliseconds added by DINOv2 in step 2 were recovered by the knob adjustments in steps 5–8. This is what the earlier statement "the cost of the DINOv2 backbone is recovered by NAS" means in numbers.
There are three things to be careful about when reading this table.
- Results can depend on order. The "+2.0" in an ablation means "the height of that step when stacked in this order". Change the order, and the height of each step can change, because the changes affect each other (for example, the lower learning rate makes sense together with DINOv2).
- Small discrepancies between tables. The last row of Table 5 (54.6) and RF-DETR (M) in Table 2 (54.7) differ by 0.1 points. The paper does not explain why.
- Discrepancies between descriptions. For the content of the "gentler training settings", the paper's main text mentions a "larger batch" while the caption of Table 5 mentions a "smaller batch". Appendix A states a batch size of 128, the same as LW-DETR. The tutorial could not confirm which is correct, so the description above includes only the learning rate and normalization, on which all three agree.
The order in which this tutorial builds things up
This chapter has passed over many unfamiliar terms: IoU, AP, attention, queries, Hungarian matching, deformable attention, window attention, weight-sharing NAS. The remaining chapters fill these in one at a time, with hand calculations and running code. The order is not to take RF-DETR apart from the outside in, but to build from the bottom-level components up, one at a time, until the result is RF-DETR. Figure 1-9 of the original tutorial is a map of these four stages (Stage 1, fundamentals, Chapters 2–6; Stage 2, the DETR lineage, Chapters 7–9; Stage 3, RF-DETR, Chapters 10–13; Stage 4, practice, Chapters 14–15) with a band beneath them reading "build a mini RF-DETR in Shape World". The current Chapter 1 is the entrance to Stage 1, and the "mini RF-DETR" for Shape World is completed in Stage 3, drawn with a bold border.
Stage 1: Fundamentals (Chapters 02–06)
- Chapter 2: Boxes and IoU: Two ways to write a box as four numbers, IoU for measuring how much two boxes overlap, and its improved variant GIoU. All of a detector's losses and scoring rest on this.
- Chapter 3: Scoring detectors: AP and mAP: Compute by hand the AP that appears in this chapter's tables. NMS is also implemented here.
- Chapter 4: Deep learning basics and classification losses: The basics of neural networks and training, and the focal loss for taming class imbalance.
- Chapter 5: Attention and the Transformer: Work out "tokens attend to each other" by hand with numbers. Half of Figure 1-7 is this operation.
- Chapter 6: Vision Transformer and DINOv2: How to cut an image into patches and feed it to a Transformer, and how to learn in advance without labels.
Stage 2: The DETR lineage (Chapters 07–09)
- Chapter 7: DETR: Set prediction and Hungarian matching. Build your first NMS-free detector in Shape World and see for yourself why training is slow.
- Chapter 8: Deformable DETR: Implement deformable attention, which looks only where needed, from scratch.
- Chapter 9: Real-time DETRs: RT-DETR and LW-DETR: Window attention, the projector, and other components RF-DETR inherited.
Stage 3: RF-DETR (Chapters 10–13)
- Chapter 10: RF-DETR's architecture: Fill in Figure 1-7 with code, one cell at a time, following the tensor shapes.
- Chapter 11: Training RF-DETR: The full loss and training tips. Train a mini RF-DETR in Shape World.
- Chapter 12: Weight-sharing NAS: Train while turning the knobs, evaluate hundreds of configurations, and draw the Pareto curve yourself.
- Chapter 13: RF-DETR-Seg: Attach a segmentation head to predict the shapes' masks as well.
Stage 4: Practice (Chapters 14–15)
- Chapter 14: Practice: the rfdetr package: Run inference with the real released RF-DETR, fine-tune it on your own data, and export it for deployment.
- Chapter 15: Appendix: A troubleshooting checklist, a collection of formulas, a glossary, and further papers to read.
The tutorial keeps one promise throughout: build and run every component of RF-DETR yourself in Shape World. The real RF-DETR has over 30 million parameters and needs several GPUs to train on COCO, but a "mini RF-DETR" scaled down for 96×96 shape images trains in a dozen or so minutes on a single laptop GPU. It is small, but its architecture and losses follow the same principles. After getting a hands-on feel for the principles with the small version, you meet the real thing in Chapter 14. However, results from the mini experiments and results the paper reports on COCO are different things, so the tutorial always keeps "in this tutorial's experiments" and "in the paper" separate.
Summary
- Object detection is the problem of answering a box and a class for each object in an image, and a detector's output is a set of (box, class, score), \(\{(b_i, c_i, s_i)\}\). Its size varies by image and it has no order.
- Five things make detection hard: unknown count, varied size and position, duplicate predictions, class imbalance (mostly background), and speed.
- Two-stage detectors (the R-CNN family) generate region proposals and then classify them; one-stage detectors (YOLO, SSD) predict in one pass from grids and anchors. Both rely on hand-designed components such as anchors and NMS.
- DETR (2020) treats detection as set prediction, matches predictions to ground truth one-to-one, and trains end-to-end without NMS. Deformable DETR, RT-DETR, and LW-DETR in turn eased its slow training and heavy computation.
- Real-time performance is measured by latency (milliseconds per image). Accuracy and latency trade off against each other, and the line joining the models not dominated by any other model is the Pareto curve.
- RF-DETR (2025, ICLR 2026) plugs a DINOv2 backbone into LW-DETR, adds weight-sharing NAS that trains while turning five knobs (resolution, patch size, number of windows, number of decoder layers, number of queries), and standardizes latency measurement.
- The paper's concern is that "specialist detectors are overfit to COCO", so it evaluates on RF100-VL, a set of 100 datasets, alongside COCO. This is the paper's claim.
- Paper figures: RF-DETR (N) 48.0 AP at 2.3 ms (+5.3 over D-FINE (N)), (2XL) 60.1 AP at 17.2 ms. However, at M and above there are sizes where D-FINE has slightly higher COCO AP.
Exercises
- 1. A photo shows three apples and one banana. What does each of (a) image classification, (b) object detection, and (c) instance segmentation output as its answer? For which of them does the "number" of answers vary from photo to photo?
- (a) "There are apples and a banana": classes for the whole image. It does not say how many or where. (b) 4 boxes (3 apples, 1 banana), each with a class and score. (c) 4 masks (3 apples, 1 banana), each with a class and score; the three apples are painted separately as different instances. The number of answers varies by photo for (b) and (c). (a) is a fixed output, one per class.
- 2. A ground-truth box in Shape World (96×96) is \((c_x, c_y, w, h) = (0.25, 0.50, 0.50, 0.25)\). Convert the box's center, width, and height to pixels, and find the horizontal coordinates of the box's left and right edges.
- Multiply by 96. Center \((0.25 \times 96,\; 0.50 \times 96) = (24, 48)\), width \(0.50 \times 96 = 48\), height \(0.25 \times 96 = 24\) pixels. The left edge is the center minus half the width, \(24 - 24 = 0\), and the right edge is \(24 + 24 = 48\). It is a flat box spanning the full width of the left half of the image (in actual Shape World images, shapes are kept slightly away from the edges, so such a box never occurs; this is for calculation practice).
- 3. Divide an image into an 8×8 grid with one candidate per cell. If the image has 3 objects whose centers are all in different cells, how many candidates have "nothing" as the correct answer, and what percentage of the total is that? If the detector simply answers "nothing everywhere", what is its per-candidate accuracy, and why is this a problem?
- There are \(8 \times 8 = 64\) candidates, and 3 are responsible for objects, so \(64 - 3 = 61\) are "nothing", or \(61 / 64 \approx 95.3\%\). Answering "nothing everywhere" gets 95.3% of the candidates right. But it finds no objects at all, so it is useless as a detector. Preventing training from drifting toward such "easy answers" is the class imbalance problem (the focal loss in Chapter 4).
- 4. You want to attach a detector to a camera that shoots 60 frames per second. (1) How many milliseconds are available per image? (2) If processing other than the detector takes 6 milliseconds, which is the most accurate RF-DETR size you can use from the "Configurations and performance by size" table? (3) If that model alone runs without pause, how many images per second does it process?
- (1) \(1000 \div 60 \approx 16.7\) milliseconds. (2) The time left for the detector is \(16.7 - 6 = 10.7\) milliseconds. L fits at 6.8 milliseconds, and XL overflows at 11.5 milliseconds. So the answer is L (56.5 AP). (3) \(1000 \div 6.8 \approx 147\) images. Note that the table's latencies were measured with TensorRT FP16 on a T4 GPU, so on other hardware you need to measure for yourself.
- 5. The (latency ms, COCO AP) of five models are YOLO11 (M) (5.1, 48.3), RT-DETR (R18) (4.4, 49.0), LW-DETR (M) (4.4, 52.6), D-FINE (M) (5.4, 55.0), and RF-DETR (M) (4.4, 54.7). Pick all models on the Pareto frontier, and say which model dominates each of the rest.
- The models on the Pareto frontier are RF-DETR (M) and D-FINE (M). RF-DETR (M) has the highest AP (54.7) at 4.4 milliseconds, the fastest of the five. D-FINE (M) is slower (5.4) but has a higher AP (55.0), so it is not dominated by RF-DETR (M). RT-DETR (R18) and LW-DETR (M) have lower AP than RF-DETR (M) at the same latency, so they are dominated. YOLO11 (M) is both slower and lower in AP than RF-DETR (M), so it is dominated (this applies within these five; adding models of other sizes changes the frontier).
- 6. The RF-DETR paper states that on COCO it evaluated every combination of 11 resolutions, 7 patch sizes, 7 decoder layer counts (0–6 layers), 3 window counts, and 4 query counts. How many combinations are there in total? Why don't they each have to be trained separately?
- \(11 \times 7 \times 7 \times 3 \times 4 = 6468\) combinations (\(11 \times 7 = 77\), \(77 \times 7 = 539\), \(539 \times 3 = 1617\), \(1617 \times 4 = 6468\)). During training, a single set of weights was updated while turning the knobs at random at every step, so those weights work reasonably well whichever combination they are set to (weight-sharing NAS). So after training, you only need to measure accuracy and latency for each combination. Details are covered in Chapter 12.
- 7. Explain why detectors like YOLO need NMS while the DETR family does not, in terms of the difference in "how ground truth is assigned to predictions during training".
- In grid- and anchor-based methods, several candidates near one object are not penalized during training for each predicting that object (in fact the same ground truth is sometimes assigned to several candidates), so at inference one object gets several predictions. They must therefore be removed afterward by a rule (NMS). DETR assigns each ground-truth object one-to-one to exactly one prediction, and the remaining predictions get "no object" as their target. Queries that redundantly predict the same object are penalized, so after training, duplicates do not appear in the first place.
The next chapter, Boxes and IoU, starts from the most basic component. A detector's answer is a box, and to say whether a box is right or wrong you first need to be able to measure "how similar two boxes are" as a number, so you will work out by hand, and then build in code, how to write boxes and how to measure overlap.
See also
- RF-DETR:Tutorial
- RF-DETR
- RF-DETR:Review
- Object detection
- Instance segmentation
- R-CNN
- Faster R-CNN
- Mask R-CNN
- YOLO
- GroundingDINO
- DINOv2
- COCO
- Roboflow
Favorite site
- 01. What Is RF-DETR
- Robinson et al., RF-DETR: Neural Architecture Search for Real-Time Detection Transformers (2025)
- Girshick et al., R-CNN (2013)
- Ren et al., Faster R-CNN (2015)
- Redmon et al., You Only Look Once (2015)
- Liu et al., SSD (2015)
- He et al., Mask R-CNN (2017)
- Lin et al., Focal Loss for Dense Object Detection (RetinaNet, 2017)
- Carion et al., End-to-End Object Detection with Transformers (DETR, 2020)
- Zhu et al., Deformable DETR (2020)
- Zhao et al., DETRs Beat YOLOs on Real-time Object Detection (RT-DETR, 2023)
- Chen et al., LW-DETR (2024)
- Peng et al., D-FINE (2024)
- Oquab et al., DINOv2 (2023)
- Liu et al., Grounding DINO (2023)
- Lin et al., Microsoft COCO (2014)
- Robicheaux et al., Roboflow100-VL (2025)